SkyScribe
Who Is the Company Behind SkyScribe?
- Seller: SkyScribe
- HQ Location: N/A
-
LinkedIn® Page: www.linkedin.com
1 employees on LinkedIn®
Total Products under this Category: 337
Last updated: September 15, 2026
Why You Can Trust G2's Software Rankings:
G2's software rankings are built on verified user reviews, rigorous moderation, and a consistent research methodology maintained by a team of analysts and data experts. Each product is measured using the same transparent criteria, with no paid placement or vendor influence. While reviews reflect real user experiences, which can be subjective, they offer valuable insight into how software performs in the hands of professionals. Together, these inputs power the G2 Score, a standardized way to compare tools within every category.
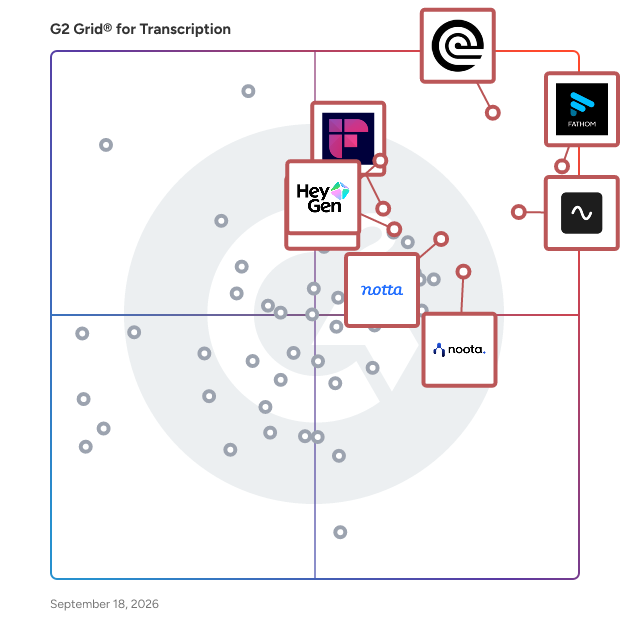
Highlighted products: Fathom, Rev, Riverside, Otter.ai, Notta, Noota, Fireflies.ai, and HeyGen.
Underlying data: [Grid® JSON](https://www.g2.com/categories/transcription/grids.json?focus%5B%5D=fathom-video&focus%5B%5D=rev&focus%5B%5D=riverside&focus%5B%5D=otter-ai&focus%5B%5D=notta&focus%5B%5D=noota&focus%5B%5D=fireflies-ai&focus%5B%5D=heygen)
SmartCaptions is a powerful Adobe Premiere Pro extension that turns your audio into accurate, time-coded transcripts. Edit faster, create better content, and save time with our AI-powered transcription.
Snackable AI is a cloud-based platform that finds the most powerful moments in your video (like webinars) and audio (like podcasts) FOR you, so you can share those insights faster than ever before. * navigate long video easily with AI-generated chapters and transcripts * let AI highlight key moments (snacks) for you automatically * share them as engaging short clips (audiograms) seamlessly * organize everything in one media library
Transcription software for automated audio and video transcription, delivered to your inbox in minutes.
Speechdash is transcription software that converts audio and video files into text. The platform supports multiple file formats, including MP3, MP4, WAV, AAC, M4A, MOV, OGG, OPUS, MPEG, WMA, and WMV. Speechdash also processes PDF documents, providing versatility in file handling. The speaker recognition feature labels different speakers in recordings, which can be useful for interviews and meetings. Files up to ten hours long can be uploaded to the platform. The drag-and-drop interface allows users to upload media files directly. Security measures are in place to protect data privacy during the transcription process. Speechdash operates on a free-to-start model that does not require a credit card to begin using the service.
"SpeechFlow is a cutting-edge speech-to-text tool that empowers businesses and individuals with unparalleled accuracy and efficiency. Our advanced AI technology ensures precise transcription of audio and video content into written text, supporting up to 14 languages, beyond just English. Main Features: Multilingual Transcriptions: Overcome language barriers with support for 14 languages. Get accurate and reliable transcriptions in diverse linguistic contexts. All-in-One Transcription Solution: API & Online Platform:For enterprises and individuals, SpeechFlow offers a speech recognition API interface and online transcription features, which are simple and easy to use. Accurate Transcriptions: Benefit from industry-leading accuracy, understanding industry-specific terminology, and context for comprehensive and reliable transcriptions. Industry-Specific Models: Tailored to meet the unique needs of various sectors, our well-trained speech recognition models enhance operational efficiency in healthcare, finance, legal, customer service, and education. Lightning-Fast Processing: Experience rapid transcriptions, with 1 hour of audio transcribed in under 3 minutes, saving you valuable time. Free extended trial every month:5 hours of free speech-to-text transcription per user per month Cost-Effective Pricing: Prices as low as $0.0002 per second,pay only for what you use with our flexible pay-as-you-go pricing Main Applicability: Contact Centers: Extract valuable insights from customer conversations, improve agent productivity, and reduce costs. Video Captioning: Enhance accessibility and reach a broader audience with accurate video transcriptions. Virtual Meetings: Easily transcribe meetings and get insights from every discussion, regardless of background noise. Media Monitoring: Build a safer platform by detecting sensitive content like hate speech and profanity with high accuracy. Content Creators: Effortlessly transcribe interviews and lectures for focused analysis. Translators and Interpreters: Enhance workflow and deliver precise translations. Requirements for Use: SpeechFlow top-notch accuracy, fast processing, multilingual support, and cost-effective pricing make SpeechFlow the ultimate choice for all your speech-to-text needs. Click now to streamline your transcription process and take your business to the next level with SpeechFlow!"
Average Rating: 4.4/5.0
Total Reviews: 6
AI-generated summary from verified user reviews
"User friendly and helpful to usè"
Rating: 4.5/5.0 stars
— Sana F.
"Most effective speech-to-text API service!"
Rating: 4.0/5.0 stars
— ANUROOP F.
Speech to Text is an advanced AI -powered audio transcription solution that automatically converts recorded calls, radio transmissions, and satellite communications into accurate, readable text. With support for over 50 languages, background noise reduction, and audio enhancement, it ensures critical information is never missed. Designed for defense, emergency, and intelligence use cases, it simplifies documentation and accelerates response times.
Spoken is a podcast transcript retrieval API designed for AI agents and LLM pipelines. Instead of transcribing raw audio with services like Deepgram, AssemblyAI, or Whisper, Spoken returns the existing transcript for any published podcast episode — already cleaned, formatted as Markdown, and labeled with real speaker names (e.g., "Andrew Huberman", "Lex Fridman") rather than anonymous diarization labels like "Speaker 1" and "Speaker 2". Developers use Spoken to build podcast summarizers, RAG pipelines over podcast content, research agents, and other tools that need access to spoken content in a form LLMs can reason about. A typical one-hour episode produces 8,000–15,000 tokens — sized to fit in most LLM context windows in a single call.
Stenobox is transcription software for court reporters — however you make the record. It turns court and deposition audio into a court-formatted verbatim draft that you review against the audio and certify as the officer of the record. Upload MP3, WAV, M4A, video or FTR court recorder folders, or record the proceeding in the browser. A live draft updates as people speak and can be shared through a private link that expires when the session ends. Drafts arrive with court-standard structure: Q./A. and speaker labels, examination headers, numbered lines, and dates and numbers formatted by the book. Interpreted proceedings are supported. Doubtful words are flagged and linked to their audio, and speaker checks catch voice mismatches, so you verify by listening instead of retyping. Review with a USB foot pedal, quiet-voice boost, silence skipping and synced video. Export to Word or plain text with title, contents and certificate pages. Audio is never reused for anything else.
What is Subanana? Subanana is an AI-powered speech-to-text platform built for content creators, businesses, and teams who need fast, accurate subtitles, transcriptions, and live captions across 80+ languages. Trusted by over 100,000 users and teams — and the most widely adopted AI subtitle and transcription tool in Hong Kong — Subanana turns spoken content into polished, actionable text in minutes. Subtitling Made Simple Subanana generates precise AI subtitles from YouTube links, uploaded video/audio files, or in-app recordings. Its built-in subtitle editor lets users review and adjust text and timecodes directly in the browser, then export in multiple formats including SRT, DOCX, CSV, and TXT. Users can also download videos with subtitles already embedded — no post-production software required. Meeting & Interview Transcription For professionals and remote teams, Subanana transcribes meetings and interviews with automatic speaker identification. Users can upload recordings, paste a YouTube link, record directly, or connect their Google Calendar to schedule a recording bot for Google Meet and Microsoft Teams calls. Beyond verbatim transcripts, Subanana's AI generates meeting summaries, action items, and chapter highlights — giving teams a complete, searchable record of every conversation. Users can also chat with the AI to instantly locate key details within their meetings. Live Transcription & Translation Subanana enables real-time speech-to-text captioning for conferences, multilingual events, and cross-border collaboration. Audio is transcribed and translated live, with bilingual content displayed side by side on Subanana's web and mobile interface. Attendees can join via QR code to follow along on their own devices. Transcription and translation results are saved for later review, while audio is never stored — keeping sensitive conversations private. Why Teams Choose Subanana Subanana delivers up to 99% accuracy as reported by users, with the team continuously benchmarking the latest AI models on a weekly basis. The platform supports free and paid plans — free users can process the first 15 minutes of any file, while subscribers unlock files up to 15 GB, watermark-free exports, and up to 4K video output. Paid plans start at $9/month with no commitment — cancel anytime. Whether you're a YouTuber adding multilingual subtitles, a team documenting every meeting, or an event organizer captioning a live conference, Subanana is the all-in-one AI platform that turns speech into content.
Subgrab is a video transcript extraction tool that converts spoken audio and captions into downloadable text files. The platform supports 28 video services, including YouTube, TikTok, Vimeo, Twitch, Instagram, Facebook, Loom, LinkedIn, Dailymotion, and SoundCloud. For videos with existing captions, Subgrab retrieves and extracts text instantly. When captions are unavailable, the AI transcription engine converts audio into text across 90+ languages. Transcripts can be downloaded in plain text, SubRip, or WebVTT formats, all with timestamps for navigation. The platform generates AI-powered summaries with key takeaways, chapter markers, and quotes from video content. Audio files are deleted after processing, and video files are not stored on the platform. New accounts receive free credits upon signup, providing access to core features without requiring software installation or browser extensions.
