Learn More About Synthetic Data Tools
Synthetic data software refers to tools and platforms designed to generate artificial datasets that replicate the statistical properties and patterns of real-world data. Unlike traditional data sources, synthetic data is entirely artificial, created to mimic the characteristics of actual data without containing sensitive or personally identifiable information (PII). This approach helps organizations adhere to various privacy regulations, such as the General Data Protection Regulation (GDPR).
These software tools are commonly used to augment datasets, simulate events, and address class imbalances, providing a cost-effective solution to data scarcity. By using synthetic data, businesses can safely test algorithms, predictive models, applications, and systems without the risks associated with real data. This not only protects privacy but also enhances compliance with data protection laws. Buyers in regulated industries also compare synthetic data platforms for audit logs and financial services compliance. Based on G2 reviews, users, consultants, and administrators evaluate synthetic data software by comparing masking of sensitive data, referential integrity across related tables, and the setup effort that complex schemas demand.
What is synthetic data generation?
Synthetic data generation is the process of creating artificial data that reflects the statistical properties of real datasets. This method is particularly useful when developing a dataset from scratch would be too time-consuming and costly, often resulting in incomplete or inaccurate data. Synthetic data generation tools make this process easier, allowing developers to quickly create accurate and detailed datasets with the required variables.
Synthetic dataset generation serves several key purposes, such as enhancing data privacy, improving machine learning (ML) models, supporting legal research, detecting fraud, and testing software applications. It empowers organizations to innovate and analyze while minimizing the risks associated with using real data.
How to generate synthetic data
Below is a general overview of the steps involved in generating synthetic data.
-
Define the data requirements: Start by identifying your needs (training machine learning models, testing algorithms, or validating data pipelines), data type (like images, text, or numerical), and required data characteristics (size, format, and distribution). Also, establish the required volume of synthetic data.
-
Choose a generation method: Select a generation method. There are three main approaches you can choose from:
-Statistical modeling: By analyzing real data, data scientists identify its underlying statistical patterns (for example: normal or exponential). They then generate synthetic data that follows these distributions, creating a dataset that mirrors the original.
-Model-based: Machine learning models are trained on real data to learn its characteristics. Once trained, these models can generate synthetic data that mimics the statistical patterns of the original. This approach is useful for creating hybrid datasets.
-Deep learning methods: Advanced techniques like GANs and variational autoencoders (VAEs) generate high-quality synthetic data, especially for complex data types like images or time series.
-
Prepare the training data: Gather a representative dataset to simulate real-world scenarios. Ensure this data is cleaned and preprocessed for effective training.
-
Train the model: Choose a suitable algorithm and train your model by feeding it the prepared data, allowing it to learn the relevant patterns.
-
Generate synthetic data: Input the desired attributes and volume into the trained model to produce new synthetic data that mimics real-world patterns.
-
Evaluate and refine: Evaluate the quality of the generated data to ensure it meets standards. If necessary, refine the model or retrain it to improve results.
-
Additional considerations: Ensure the synthetic data generation process adheres to privacy regulations and ethical guidelines and protects individual identities. Address any biases to ensure fair representation, and strive for realism, especially when the data is used for training AI or testing software.
Who uses synthetic data software?
Several types of individual developers and teams within organizations can benefit from employing synthetic data software. The most common users are detailed here.
-
Data scientists may use synthetic data generation tools to research new ideas without the need for access to real-world data sets and without spending a lot of time assembling sets from different sources.
-
Compliance managers may use synthetic data software to create non-identifiable data sets for testing and validating compliance with data protection regulations. Doing so promises privacy and security without exposing real personal information or sensitive data.
-
Software developers turn to generation tools to speed up debugging and software creation processes by giving developers realistic data sets to complete. This type of software can also be useful for prototyping applications when real data may not be available yet.
Synthetic data software pricing
Synthetic data software is typically broken into three different pricing models.
-
Subscription-based model: Users pay a recurring fee to access all features at regular intervals, such as monthly or annually.
-
Pay-per-use model: This model allows users to pay based on their usage, data storage, seats, or consumption.
-
Tiered model: This type of model offers multiple pricing levels or "tiers," each with a different set of features or usage limits. Users can choose a tier that best fits their needs and budget, often ranging from basic to premium options.
Like most software, the price changes depending on factors such as the complexity of the program and the features it offers. Before investing in a synthetic data tool, companies need to figure out their specific needs and the features on their must-have list for more clarity.
Challenges with synthetic data solutions
Despite the numerous benefits users experience from synthetic data software, some challenges exist, too.
-
Data growth: As the volume of data grows, the process of synthetic data generation via generative AI needs to scale appropriately. This process can be intensive and may require a variety of resources in terms of processing power and storage. Additionally, sustaining the quality of synthetic data as the dataset grows becomes more complex. Larger data sets require more sophisticated models to keep up accuracy and relevance.
-
Data security and compliance: If the generated data is not properly handled, it can lead to potential security breaches where sensitive information may be leaked. Moreover, some synthetic data generation tools don’t adhere to existing privacy regulations such as GDPR or the California Consumer Privacy Act (CCPA).
-
Data preservation: Ensuring that synthetic data preserves and maintains the original’s essential properties, patterns, and relationships over time can be difficult, but it has to be done in order for synthetic data to remain useful and relevant for its intended applications.
-
Data storage and retrieval cost: Synthetic data generation tools may incur additional costs for storage and retrieval due to the use of cloud computing or ML algorithms. Companies end up going over budget because they fail to account for these costs during the planning process.
-
Data accessibility and format compatibility: Keeping synthetic data easily accessible across different systems and applications requires consistent, standardized formats. However, diverse software environments and varying data storage solutions can lead to compatibility issues. Further, as data standards evolve, maintaining compatibility with new formats while preserving accessibility to historical data becomes complicated.
How to choose the best synthetic data generation tool
The following explains the step-by-step process buyers can use to find suitable synthetic data tools for their businesses.
Identify business needs and priorities
Before choosing a synthetic data tool, companies should identify their top priorities for a tool and what exactly they’ll be using it for. Clear goals and requirements make the selection process easier and more efficient, especially as more options hit the market. Because to consider factors like data quality, compliance and security, customization, and scalability.
Choose the necessary technology and features
Next, companies work on narrowing down the features and functionalities they need most. Some essential technology and features a company may be looking for are discussed here.
-
Generative adversarial networks for creating highly realistic synthetic data by training models to generate data that closely mimics real data.
-
Customizable parameters that allow users to tailor data generation to specific needs, such as adjusting distributions, correlations, and noise levels.
-
APIs and SDKs that provide easy integration with existing systems, databases, and workflows.
-
Regulatory compliance to ensure software adheres to data protection regulations such as GDPR and Health Insurance Portability and Accountability Act (HIPAA).
-
Scenario simulation for the ability to simulate various hypothetical scenarios for testing and analysis.
-
Quality assurance features to validate the accuracy and quality of data.
When companies have a short list of services based on their requirements and must-have functionalities, it’s easier to refine which options best suit their needs.
Review vendor vision, roadmap, viability, and support
In this stage, you can start vetting the selected synthetic data software vendors and conduct demos to determine if a product meets your requirements. For the best outcome, a buyer should share detailed requirements in advance so providers know which features and functionalities to showcase.
Below are some meaningful questions buyers can ask synthetic data generation companies as a part of the decision process.
- What kind of data does the tool generate? Is it exclusively structured data or can it generate unstructured data, like images and videos?
- How accurately does the software replicate the statistical properties and complexity of real data?
- Can the solution handle large-scale data generation and maintain performance and quality as data volumes grow?
- How does the tool handle missing values? Is there an option to fill in missing values with realistic replacements?
- Is the output format customizable? Can you specify a preferred output format for your dataset?
- How does the software ensure compliance with data protection regulations like GDPR and HIPAA?
- How does security and privacy fit into synthetic data generation? To avoid security breaches, does the tool offer any safeguards against unauthorized access of generated data sets?
- Is there a support system to help users if they encounter or discover any issues? Are tutorials, FAQs, or customer service provided if necessary?
Evaluate the deployment and purchasing model
Once you’ve received answers to the above questions and are ready to move on to the next stage, loop in your key stakeholders and at least one employee from each department who will be using the software.
For example, with synthetic data software, it’s best that the buyer loops in the developers who will be using the software to ensure it covers the core features your business is looking for in synthetic data sets.
Put it all together
The buyer makes the final decision after getting buy-in from everyone on the selection committee, including end users. The buy-in is essential for getting everyone on the same page regarding implementation, onboarding, and potential use cases.
Synthetic test data generation software trends
Some recent trends that were recently seen in the field of synthetic data software are as follows.
-
Integration with the machine learning pipeline: Synthetic data tools are increasingly designed to automatically generate and ingest data directly into machine learning pipelines. Automation like this reduces the time and effort required to prepare training data, which lets data scientists focus on model development and optimization.
-
Automated data generation platforms: Automated synthetic data generation tools are becoming popular for their ability to quickly and accurately make large amounts of realistic data. They permit users to create realistic data sets with minimal effort, enabling them to come up with intricate scenarios and test new models efficiently.
-
Generative AI in synthetic data: The use of Generative AI, using techniques like GANs and VAEs, is transforming the synthetic data field by creating high-quality artificial datasets that mimic real data. It enhances data quality, automates generation, and allows for diverse, customizable datasets while protecting privacy.
Synthetic Data Software FAQs
Most Popular FAQs
Which synthetic data software has the best reviews?
Ratings in this category are high, but most rest on small review counts, so the most trusted synthetic data generators based on user reviews are hard to single out: K2View is the only product with more than 3 reviews written or updated in the past year.
-
K2View: Rated 4.6 out of 5 across 55 reviews, and its 6 past-year reviews often praise an easy interface and the way it provisions realistic test data.
-
Syntho: Rated 4.6 across 16 reviews, none written or updated in the past year, so its rating reflects older feedback.
-
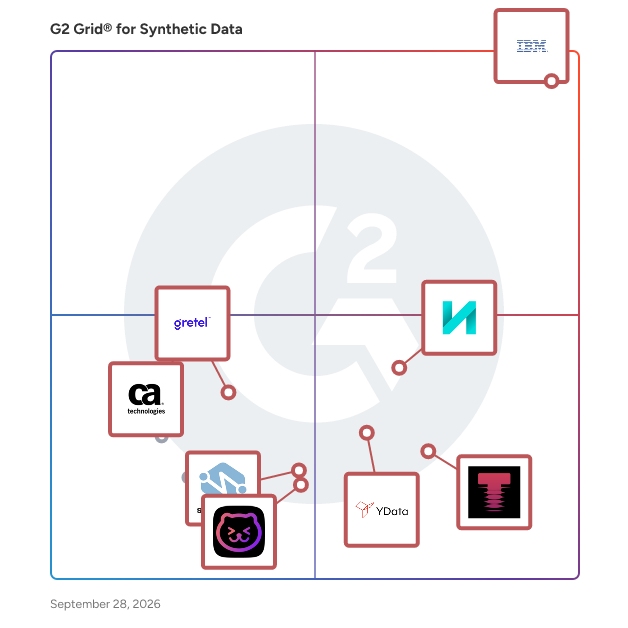
YData: Rated 4.6 across 12 reviews and fourth by G2 Score in the Fall 2026 Grid Report for Synthetic Data.
-
Tumult Analytics: Rated 4.4 across 38 reviews, with a Satisfaction score of 76 in the same Grid Report.
Synthetic data vs real data: what is the difference?
Real data records actual people, transactions, or events, while synthetic data is generated by a model to copy the statistical patterns of that real data without carrying the original records. The tradeoff is fidelity: Synthetic data is only as useful as its match to the source. In the past year, 4 of the 15 synthetic data reviews on G2 praise tools for keeping referential integrity or statistical accuracy close to the original, which is what lets synthetic tables stand in for production data in testing and model training. Real data is still the benchmark, so it makes sense to validate synthetic output against it before relying on it.
Which synthetic data platforms connect directly to Snowflake and BigQuery without manual ETL pipelines?
None of the 15 synthetic data reviews written or updated on G2 in the past year mentions Snowflake or BigQuery, so the options below rest on vendor documentation. Each offers built-in connectors for both warehouses, which can replace manual ETL pipelines for moving source data in and synthetic data out.
-
MOSTLY AI Synthetic Data Platform: Per the vendor, its Snowflake and Google BigQuery connectors work both as data sources for training generators and as destinations for the synthetic output.
-
YData: Per the vendor, YData Fabric includes Snowflake and Google BigQuery connectors and can read a whole Snowflake schema or a single query.
-
IBM watsonx.ai: Per the vendor, its Synthetic Data Generator imports source data through watsonx.ai connections, which include Snowflake and Google BigQuery.
Test each connector against your own warehouse permissions during a trial.
Which synthetic data generators use schema inference to reduce setup time from hours to minutes?
Tonic.ai has the most review evidence for automatic schema detection; for other tools, schema inference is mostly a vendor claim so far. Setup time is still the most common complaint in this category: 5 of the 15 past-year reviews on G2 mention setup effort or complex schemas.
-
Tonic.ai: Several reviewers credit automatic schema generation from the data source and automated detection of schema changes, though some say complex schemas still take time to configure.
-
Syntho: Reviewers describe quick deployment with little manual work, while a few note that relationships between tables still have to be set up by hand.
-
GenRocket: Per the vendor, its self-service platform lets users model, design, and deploy test data on demand.
Hazy also detects data types automatically, per the vendor, but has no G2 reviews yet.
Is synthetic data GDPR compliant?
It can be, but generating data synthetically does not settle the question on its own. This question reflects a dominant pattern across search results for this category rather than a single source. Search results agree that GDPR turns on whether a person can be identified, so synthetic records that closely copy real ones, or that a model memorized, may still count as personal data. The safer path is to test re-identification risk, document the method, and repeat the check as generation techniques change. Reviews point the same way: 3 of the 15 synthetic data reviews on G2 from the past year mention compliance or regulated health data, and 5 praise masking or de-identification.
Small Business FAQs
What is the most affordable synthetic data software for SMBs?
Free and open-source options are the most affordable small business synthetic data software, and price rarely comes up in reviews: only 2 of the 15 past-year synthetic data reviews on G2 mention cost.
-
Tumult Analytics: An open-source Python library, per the vendor, so teams that work in code pay no license fee; it is rated 4.4 out of 5 across 38 reviews.
-
MOSTLY AI: Per the vendor, its Synthetic Data SDK is free and open source under the Apache 2.0 license and runs on a team's own hardware.
-
YData: Per the vendor, the Fabric Community plan is free, with limits of 1 project and datasets up to 50 columns and 100,000 rows.
-
GenRocket: The vendor describes its license and implementation costs as attractive for test data teams.
What is the best synthetic data software for startups?
For startups, the best synthetic data tools for small businesses are developer-friendly options that are quick to try. Synthetic data generator reviews from data engineering teams that cover Gretel, Tonic, MOSTLY AI, and Hazy are still scarce on G2, so the Gretel.ai vs. Tonic.ai comparison is the quickest way to see two of them side by side.
-
Gretel.ai: Rated 4.4 across 13 reviews, and per the vendor, it is built for developers to experiment and build safely with data.
-
YData: Rated 4.6 across 12 reviews, and per the vendor, it helps data science teams build better datasets for AI.
-
Tumult Analytics: Per the vendor, its Python APIs feel familiar to Pandas and PySpark users, which suits startups already working in Python.
Which synthetic data software is the most user-friendly for startups?
Syntho, Gretel.ai, and Tonic.ai collect the most consistent ease-of-use praise from G2 reviewers, though most of these reviews are more than a year old because the category's recent review base is small.
-
Syntho: Rated 4.6 out of 5 across 16 reviews, mostly from small businesses, with reviewers calling it user-friendly and quick to learn even with little synthetic data background; a few note that complex, multi-table data still needs manual work.
-
Gretel.ai: Rated 4.4 out of 5 across 13 reviews, where the user-friendly interface is the most repeated praise, though a few reviewers say some machine learning knowledge helps.
-
Tonic.ai: Rated 4.2 out of 5 across 38 reviews, with many calling it easy to use for generating test data, while several describe a learning curve when configuring complex schemas.
Can a small business use synthetic data for software testing?
Yes, and testing is the most common use case for small business synthetic data options and larger tools alike: 6 of the 15 past-year reviews describe generating or provisioning test data, often to keep customer information out of development and QA work. Synthetic test data also helps when production data is not available yet, which suits early-stage products. Look for masking or de-identification, which 5 reviews praise, and check that related tables stay consistent, since 4 reviews single out referential integrity as a key benefit.
What should a small business look for in a synthetic data tool?
A small business should weigh the same basics that show up across small business synthetic data platforms: Ease of use, masking, and setup effort, with priority for synthetic data tools that offer granular PII masking controls when customer records are involved. In the past year, 6 of the 15 synthetic data reviews praise an intuitive interface, 5 praise masking or de-identification, and 5 complain about setup work. Pricing is the gap: Only 2 reviews mention cost, so ask vendors for small-team plans. If you plan to train models, also check how the tool shows that its output stays close to the source data.
Enterprise FAQs
What is the best-rated synthetic data software for tech enterprises?
Among enterprise synthetic data software, K2View draws most of the recent enterprise feedback, while the other options rest on older or vendor-supplied information. Among the highest rated synthetic data platforms for ML development with low compliance risk, IBM watsonx.ai leads the Fall 2026 Grid Report, though compliance risk still depends on how each tool handles personal data.
-
K2View: Rated 4.6 across 55 reviews, and 5 of the 6 past-year enterprise reviews cover it, often praising its interface and test data provisioning.
-
IBM watsonx.ai: Rated 4.4 across 151 reviews and first by G2 Score in the Fall 2026 Grid Report, though its reviews center on model building rather than synthetic data.
-
Perforce Delphix: Rated 4.1 across 11 reviews, and per the vendor, it pairs data masking with data virtualization for non-production environments.
-
CA Test Data Manager: Rated 4.0 across 21 reviews, and per the vendor, it combines subsetting, masking, synthetic generation, and cloning for testing teams.
What is the most reliable synthetic data software for enterprises?
Reliability is rarely discussed in synthetic data reviews from enterprise companies: Past-year reviews mention data integrity more than uptime, so judge reliability through a proof of concept on your own schemas. Here are some top picks for the most reliable synthetic data software for enterprises:
-
Perforce Delphix: Per the vendor, it helps companies recover quickly from downtime events and automates test data delivery in CI/CD.
-
CA Test Data Manager: Per the vendor, it automates creating, maintaining, and provisioning test data for continuous delivery.
-
GenRocket: Rated 4.6 across 11 reviews, and per the vendor, its test data cases and rules can be reused across projects.
What is the best-reviewed synthetic data software for enterprise app integration?
For enterprise synthetic data platforms, integration feedback in the past year comes mostly from K2View reviews, so the other options here rest on vendor information.
-
K2View: 4 of its 6 past-year reviews describe connecting multiple databases or source systems, including auto-discovery of table relationships.
-
GenRocket: Per the vendor, it deploys test data into CI/CD pipelines and supports more than 100 data formats, including SQL, JSON, Kafka, and Parquet.
-
CA Test Data Manager: Per the vendor, it fits continuous delivery workflows by provisioning test data on demand.
What compliance evidence should enterprises request from synthetic data vendors?
Enterprises need synthetic data solutions that support fintech compliance audits with documented data governance, yet few enterprise synthetic data tools have reviews that discuss audits directly: 2 of the 15 past-year synthetic data reviews come from banking or financial services, and none mentions audit logs or governance documentation, so most of what follows is per the vendor.
-
Perforce Delphix: Per the vendor, it automates compliant, masked data for DevOps and non-production environments.
-
MOSTLY AI Synthetic Data Platform: Per the vendor, it serves banking and insurance customers and generates data that does not expose individuals.
-
Tonic.ai: Per the vendor, it combines synthesis, de-identification, and subsetting and works with financial services companies.
Ask each vendor for audit logs, data lineage, and privacy reports you can hand to auditors.
What should enterprises evaluate in synthetic data software?
Based on recent G2 reviews, enterprises should evaluate the following in enterprise synthetic data software:
- Masking and de-identification: 5 of the 15 past-year reviews praise masking or anonymization, the most cited privacy feature.
- Referential integrity: 4 reviews value synthetic or masked data that keeps relationships across tables intact.
- Setup effort: 5 reviews name setup work, a learning curve, or complexity with large schemas as a downside.
- Source connectivity: 4 enterprise reviews describe connecting multiple databases and source systems.
- Audit evidence: None of the 15 reviews mentions audit logs, so request them directly from vendors.
Researched and written by Shalaka Joshi
Reviewed and edited by Aisha West
Last Updated on October 12, 2026