Best Synthetic Data Tools - Page 6

How Many Synthetic Data Tools Products Does G2 Track?

Total Products under this Category: 116

Category Stats (Sep 2026)

  • Average Rating: 4.37/5 (↓0.01 vs Aug 2026) The average rating of products in this category, based on all submitted ratings

Last updated: September 08, 2026

How Does G2 Rank Synthetic Data Tools Products?

Why You Can Trust G2's Software Rankings:

  • 30 Analysts and Data Experts
  • 500+ Authentic Reviews
  • 116+ Products
  • Unbiased Rankings

G2's software rankings are built on verified user reviews, rigorous moderation, and a consistent research methodology maintained by a team of analysts and data experts. Each product is measured using the same transparent criteria, with no paid placement or vendor influence. While reviews reflect real user experiences, which can be subjective, they offer valuable insight into how software performs in the hands of professionals. Together, these inputs power the G2 Score, a standardized way to compare tools within every category.

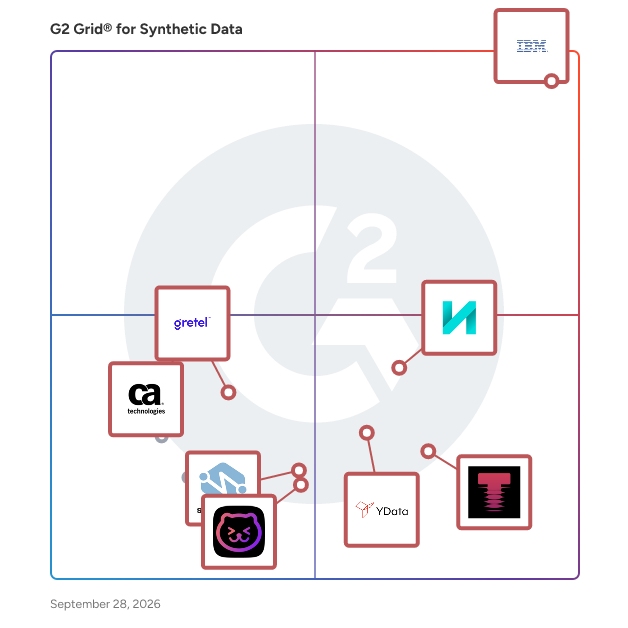
G2 Grid® for Synthetic Data Tools

G2 Grid® for Synthetic Data Tools plotting products by satisfaction and market presence

Highlighted products: IBM watsonx.ai, Tonic.ai, Tumult Analytics, YData, CA Test Data Manager, Gretel.ai, Syntheticus.ai | Synthetic Data Generator, and KopiKat.

Underlying data: [Grid® JSON](https://www.g2.com/categories/synthetic-data/grids.json?focus%5B%5D=ibm-watsonx-ai&focus%5B%5D=tonic-ai&focus%5B%5D=tumult-analytics&focus%5B%5D=ydata&focus%5B%5D=ca-test-data-manager&focus%5B%5D=gretel-ai&focus%5B%5D=syntheticus-ai-synthetic-data-generator&focus%5B%5D=kopikat)

Purify

Purify is a comprehensive machine learning (ML) platform designed to streamline data generation, model training, and inference processes. By leveraging advanced AI agents, Purify enables the creation of high-quality synthetic datasets across numerous domains, significantly reducing the time and cost associated with traditional data preparation methods. This empowers researchers and organizations to accelerate their ML research while maintaining data privacy and security. Key Features and Functionality: - Synthetic Data Engine: Utilizes state-of-the-art AI agents to produce expert-quality synthetic data, facilitating multi-modal processing and supporting over 100 different models and providers. - Secure Training: Offers enterprise-grade security and data protection during model training and fine-tuning processes. - Inference API: Enables instant deployment of models through a high-performance inference API, streamlining the transition from development to production. - Model Registry: Provides reliable versioning, storage, and management of AI models, ensuring consistency and traceability. - Distributed Training: Supports scaling of training processes across multiple GPUs, enhancing computational efficiency. - AutoML: Leverages automated machine learning to optimize model architecture and hyperparameters, compatible with frameworks like PyTorch and TensorFlow. - Model APIs: Grants access to pre-trained models via simple REST APIs, facilitating seamless integration into existing workflows. Primary Value and Problem Solved: Purify addresses the challenges associated with data preparation and model training in machine learning projects. By automating the generation of high-quality synthetic data and providing robust tools for model training and deployment, Purify reduces the technical overhead typically required in ML development. This allows researchers and organizations to focus on innovation and advancing AI research without being encumbered by complex infrastructure and data management tasks. Additionally, Purify's commitment to data privacy ensures that sensitive information remains protected throughout the ML lifecycle.

Who Is the Company Behind Purify?

Remix Labs

Remix Labs is a time-series data synthesis platform that generates new datasets from historical data, enabling modeling of rare events, stress-testing assumptions, and exploring hypothetical scenarios without manual data collection or coding expertise. Its no-code visual pipeline editor lets users create synthetic scenarios in minutes, leveraging built-in machine learning models like N-BEATS, NHITS, LSTM, and GRU to synthesize rare events, extreme conditions, and future trajectories. Users can upload data, isolate events, and create snippets as building blocks for scenario generation. The platform supports chaining pipelines for multi-stage transformations, enabling complex workflows without glue code. Applications include integration testing, model validation, and training machine learning models with augmented datasets. Managed infrastructure handles execution, while re-run capabilities ensure consistent datasets across experiments.

Who Is the Company Behind Remix Labs?

Rendered.Ai

Rendered.ai is a Platform as a Service (PaaS) designed to empower data scientists, engineers, and developers with the ability to generate unlimited, customized synthetic data for machine learning (ML) and artificial intelligence (AI) applications. By leveraging physics-based simulations, Rendered.ai addresses challenges associated with real-world data collection, such as high costs, privacy concerns, and data scarcity. This platform facilitates the creation of diverse, accurately labeled datasets, enhancing the training and validation of computer vision models across various industries. Key Features and Functionality: - Customized Synthetic Data Generation: Users can create data tailored to specific needs, effectively addressing gaps and biases in real-world datasets. - Collaborative Environment: The platform offers tools for teams to share 3D assets, sensor models, and datasets, promoting efficient collaboration. - Physically Accurate Rendering: Rendered.ai supports the use of various simulation technologies, enabling the generation of data that closely emulates real sensor imagery. - AI & ML Pipeline Integration: With an open-source framework and well-documented SDK, the platform seamlessly integrates synthetic data generation into existing AI workflows. - Cloud Resources: High-performance computing environments allow for rapid definition of data channels and dataset creation. - Cost-Effective Solution: The subscription-based model provides unlimited data generation at a fixed monthly price, reducing expenses compared to traditional data collection methods. Primary Value and Problem Solved: Rendered.ai addresses the critical challenge of obtaining high-quality, diverse, and accurately labeled datasets necessary for training robust AI and ML models. By providing a platform for generating synthetic data, it enables organizations to: - Overcome Data Scarcity: Generate data for scenarios where real-world data is limited, expensive, or impossible to acquire. - Enhance Model Accuracy: Create balanced datasets that mitigate biases inherent in real-world data, leading to more reliable AI models. - Ensure Data Privacy and Security: Produce synthetic datasets that do not contain sensitive information, thus complying with privacy regulations. - Accelerate Development Cycles: Quickly generate and iterate on datasets, reducing the time required for data collection and labeling, and speeding up the development and deployment of AI solutions. By integrating Rendered.ai into their workflows, organizations can significantly improve the efficiency and effectiveness of their AI and ML initiatives.

Who Is the Company Behind Rendered.Ai?

  • Seller: Rendered
  • Year Founded: 2019
  • HQ Location: Bellevue, US
  • LinkedIn® Page: www.linkedin.com
    19 employees on LinkedIn®

Repli5

Who Is the Company Behind Repli5?

Robotec.ai

Who Is the Company Behind Robotec.ai?

  • Seller: Robotec.ai
  • Year Founded: 2019
  • HQ Location: Warsaw, Mazowieckie, Poland
  • LinkedIn® Page: www.linkedin.com
    57 employees on LinkedIn®

SAS Data Maker

SAS Data Maker is a secure, enterprise-grade synthetic data generator designed to create statistically representative data without exposing sensitive or regulation-protected information. It enables organizations to generate synthetic data that mirrors real-world data's statistical, relational, and temporal characteristics, facilitating robust AI model development and data analysis while ensuring privacy and compliance. Key Features and Functionality: - Enterprise-Grade Trust and Capabilities: Leveraging decades of expertise in regulated industries such as banking, healthcare, and government, SAS Data Maker provides multitable source data, time series data, and differential privacy to meet enterprise-level synthetic data requirements. - No-Code Interface: The user-friendly graphical user interface (GUI) democratizes synthetic data generation, allowing business users to create and manage data without extensive technical knowledge. - Built-In Data Quality and Evaluation Tools: The solution includes tools to support various generation methods and evaluate the quality of synthetic data using visual metrics, ensuring statistical fidelity to real-world datasets. - Privacy-Enhancing Technologies (PETs): Users can seamlessly integrate synthetic data into existing workflows without significant changes, enabling the safe use of data without compromising privacy. Primary Value and User Solutions: SAS Data Maker addresses challenges related to data scarcity, privacy concerns, and regulatory compliance by providing a reliable method to generate synthetic data. This capability allows organizations to: - Accelerate AI Development: By filling gaps in training data, organizations can develop and deploy AI models more rapidly and effectively. - Enhance Data Privacy: Synthetic data generation mitigates risks associated with handling sensitive information, ensuring compliance with privacy regulations. - Reduce Costs: Organizations can minimize expenses related to data acquisition and processing by generating synthetic data instead of collecting real-world data or purchasing third-party datasets. By integrating SAS Data Maker into their data ecosystems, organizations can innovate responsibly, leveraging synthetic data to drive insights and decision-making without compromising data privacy or security.

Who Is the Company Behind SAS Data Maker?

  • Seller: SAS Institute Inc.
  • Year Founded: 1976
  • HQ Location: Cary, NC
  • Twitter: @SASsoftware
    60,863 Twitter followers
  • LinkedIn® Page: www.linkedin.com
    15,122 employees on LinkedIn®
  • Phone: 1-800-727-0025

Who Uses This Product?

  • Company Size: 100% Medium

Scale GenAI Platform

Build organizationally intelligent agents faster. Scale GenAI Platform is a comprehensive toolset to use your data to build, control, and improve your agents and AI solutions. Build AI applications and complex multi-agent systems, train agents to reason over your enterprise data, take action with your tools, and continuously improve with feedback from human-agent interactions with our Agent Monitoring Protocol.

Average Rating: 4.8/5.0

Total Reviews: 2

Who Is the Company Behind Scale GenAI Platform?

  • Seller: Scale AI
  • Year Founded: 2016
  • HQ Location: San Francisco, California, United States
  • Twitter: @scale_AI
    75,618 Twitter followers
  • LinkedIn® Page: www.linkedin.com
    5,533 employees on LinkedIn®

Who Uses This Product?

  • Company Size: 100% Medium

What Do G2 Reviewers Say About Scale GenAI Platform?

AI-generated summary from verified user reviews

Pros
  • Users appreciate the end-to-end workflow support of Scale GenAI Platform for efficiently building and deploying generative AI models.
  • Users value the comprehensive community support of Scale GenAI Platform, enhancing their experience with collaborative resources and guidance.
  • Users value the end-to-end workflow support of Scale GenAI Platform, streamlining model building and deployment processes effectively.
  • Users appreciate the end-to-end workflow support of Scale GenAI Platform, simplifying generative AI model management and deployment.
  • Users appreciate the end-to-end workflow support of Scale GenAI Platform, enabling efficient generative AI model deployment.
Cons
  • Users find the Scale GenAI Platform expensive and better suited for larger enterprises, leaving smaller teams feeling unsupported.
  • Users find the expensive subscriptions of Scale GenAI Platform overwhelming, especially for smaller teams and new users.
  • Users feel that the limited access can overwhelm smaller teams and complicate the ramp-up experience for new users.
  • Users note a lack of features for smaller teams, which can lead to feelings of being overwhelmed or under-supported.
  • Users note the limited options available, which may overwhelm smaller teams and hinder their experience with the platform.

What Are Recent G2 Reviews of Scale GenAI Platform?

Secludy

Secludy is an enterprise platform that generates privacy-guaranteed synthetic datasets for training AI models, including large language models (LLMs) and traditional machine learning (ML) systems. By creating synthetic data that mirrors real datasets, Secludy enables organizations to train, test, and evaluate AI models without exposing sensitive personal information, ensuring compliance with data protection regulations. This approach is particularly beneficial for industries like healthcare and finance, where data privacy is paramount. Key Features and Functionality: - Anonymized Synthetic Data Generation: Secludy produces privacy-guaranteed synthetic data across various formats, including structured data, unstructured text, and imaging data. This allows for safe AI model training and testing without the risk of personal data exposure. - Secure AI Gateway: The platform includes a secure AI gateway that prevents personally identifiable information (PII) leakage during inference by redacting prompts and reinserting sensitive data post-response. - Automated Documentation: Secludy offers automatic documentation tailored to regulated industries, providing evidence of leakage testing and verifiable anonymization to support compliance efforts. - Differential Privacy Implementation: Leveraging differential privacy techniques, Secludy ensures that synthetic data maintains rigorous privacy guarantees, making it suitable for use under regulations like GDPR, CCPA, and HIPAA. - One-Click Deployment: The platform is designed for easy integration, allowing for one-click deployment that seamlessly fits into existing workflows, enabling rapid generation of privacy-preserving synthetic data. - Self-Hosting Capability: Organizations can deploy Secludy within their own virtual private cloud (VPC) or on-premises environments, ensuring full control over data and compliance with internal security policies. Primary Value and User Solutions: Secludy addresses the critical challenge of utilizing sensitive data in AI development by providing a solution that generates high-fidelity synthetic data with built-in privacy guarantees. This enables organizations to: - Safely Train AI Models: Develop and fine-tune AI models using synthetic data that accurately reflects real-world datasets without compromising individual privacy. - Ensure Regulatory Compliance: Meet stringent data protection regulations by replacing real PII-bearing records with anonymized synthetic replicas, facilitating compliant data usage and sharing. - Accelerate AI Deployment: Streamline the AI development process with quick integration and deployment, reducing the time and resources required to obtain usable, compliant datasets. - Monetize Sensitive Data: Safely license and share data by providing synthetic versions that retain the utility of the original data while eliminating privacy risks, opening new avenues for data monetization. By integrating Secludy, organizations can harness the full potential of their data assets in AI initiatives while maintaining strict adherence to privacy standards and regulatory requirements.

Who Is the Company Behind Secludy?

Seedfast

Seedfast fills a development, CI, or demo database with realistic, relational test data generated from the schema itself. One command connects to your database, reads the live schema, and writes a dataset the database accepts on the first insert. Foreign keys point at rows that exist, composite keys and multi-level dependencies resolve, check and unique constraints hold, enums stay inside the values they allow, and triggers are accounted for rather than tripped over. The realism comes from reading the schema first. Seedfast works out what the data is meant to represent from table names, column names, types and constraints before it generates any of it. A table called orders with status, total_amount and placed_at gets plausible order statuses, monetary amounts on a realistic distribution rather than uniform random, and timestamps spread across a sensible window. A table called patients with date_of_birth and diagnosis_code gets medical data instead. There is no per-domain configuration to pick, and no user1@test.com placeholder filler. Scope is plain text, written in whatever language you think in: "seed 500 Slovak customers, +421 phone numbers, emails on acme.sk, invoices numbered INV-2026-0001 upward". Generated values follow the same rule. Ask for Japanese customer names and that is what the column fills with; ask for German postal addresses and they come back shaped the way German addresses are shaped, not a US layout with the words swapped out. Phone country codes, email domains you control, internal SKU patterns, prefixed invoice counters, URLs pointing at a staging host: anything a column holds can be described in a sentence and generated to match. Say nothing about any of it and Seedfast still picks a coherent default out of the schema, then holds it steady for the whole run. Volume belongs to the same scope. Fifty rows for a local branch, a million for load testing, tens of millions when the tables need to weigh what production weighs, enough to reproduce the working set of a large, high-traffic product, where index choices start to matter and a query plan that held over ten thousand rows can flip at fifty million. Realism does not degrade as the row count climbs. Nothing is copied from production, so teams in fintech, healthcare and other regulated settings can work against data that behaves like the real thing without a masking pipeline or a security review to clear first. Seedfast does not copy, mask, or de-identify existing production rows; it generates new ones. When a migration changes the schema, the next run picks it up, so there is no seed file to keep in step. The same command runs locally, as a step in a CI pipeline (GitHub Actions, GitLab CI, CircleCI), or as an MCP server that AI coding agents such as Claude and Cursor invoke as a tool. Pricing is a flat monthly plan that includes a pool of credits denominated in dollars, and each run draws from that pool by how much data it generates. No table limits, no seed limits, no per-row charges. The free plan takes no card, never expires, and refills to $5 of credits every month; paid plans are $16 and $69 a month.

Who Is the Company Behind Seedfast?

Segmed

Segmed is a platform that provides access to a vast repository of medical imaging data, enabling healthcare organizations, researchers, and developers to build and train artificial intelligence models efficiently. By aggregating and anonymizing diverse datasets from various institutions, Segmed ensures data privacy and compliance with regulatory standards. This streamlined access to high-quality, labeled medical images accelerates the development of AI applications in healthcare, facilitating advancements in diagnostics, treatment planning, and medical research. Key Features and Functionality: - Extensive Medical Imaging Dataset: Offers a comprehensive collection of anonymized medical images from multiple sources, covering various modalities and conditions. - Data Anonymization and Compliance: Ensures all data is de-identified and adheres to HIPAA and other regulatory requirements, maintaining patient confidentiality. - Customizable Data Access: Allows users to filter and select datasets based on specific criteria, such as modality, pathology, or demographic information. - Seamless Integration: Provides APIs and tools for easy integration with existing workflows and machine learning pipelines. - Scalable Infrastructure: Supports large-scale data processing and model training, accommodating the needs of both small research teams and large organizations. Primary Value and User Solutions: Segmed addresses the critical challenge of accessing diverse and high-quality medical imaging data for AI development. By providing a centralized, compliant, and user-friendly platform, it eliminates the time-consuming and complex process of data acquisition and preparation. This empowers healthcare innovators to focus on developing and deploying AI solutions that enhance diagnostic accuracy, improve patient outcomes, and drive medical research forward.

Who Is the Company Behind Segmed?

  • Seller: Segmed
  • Year Founded: 2019
  • HQ Location: Stanford, CA
  • LinkedIn® Page: www.linkedin.com
    5 employees on LinkedIn®

Sepal AI

Sepal AI is a data research company dedicated to advancing human knowledge and capabilities through the development of safe and trustworthy artificial intelligence. By partnering with leading AI laboratories and enterprises, Sepal AI focuses on creating high-quality, domain-specific datasets and evaluation frameworks that enhance model performance in real-world applications. Their platform integrates data generation tools, synthetic data augmentation, and a vast network of over 20,000 experts across various STEM fields and professional services, ensuring the production of reliable and precise datasets. Key Features and Functionality: - Curated Expert Network: Access to a diverse pool of verified professionals, including academic PhDs, medical practitioners, finance consultants, and business analysts, facilitating the creation of specialized datasets. - Integrated Data Development Platform: A unified environment that combines data generation tools, synthetic data augmentation capabilities, and quality control workflows to streamline dataset production. - Domain-Specific Dataset Creation: Tailored benchmarks, evaluations, and training data designed for specialized fields such as finance, healthcare, biology, physics, and professional services. - Flexible Remote Engagement: A gig-based participation model that allows experts to contribute on their own schedule, offering competitive hourly compensation. - Rapid Onboarding Process: A streamlined vetting system with automated identity verification and alignment consultations, granting secure access within days of profile creation. Primary Value and Solutions Provided: Sepal AI addresses the critical need for high-quality, domain-specific data in AI development, which is essential for building models that perform effectively in specialized applications. By leveraging a vast network of experts and integrating advanced data development tools, Sepal AI enables organizations to overcome the limitations of contaminated public benchmarks and generic datasets. This approach ensures the creation of reliable, accurate, and contextually relevant AI models, ultimately leading to safer and more effective AI deployments across various industries.

Who Is the Company Behind Sepal AI?

Bijou Barry
BB
Researched and written by Bijou Barry
Updated April 9, 2026