Best Synthetic Data Tools - Page 5

Last updated: April 9, 2026

How Many Synthetic Data Tools Products Does G2 Track?

Total Products under this Category: 124

Category Stats (Nov 2026)

  • Average Rating: 4.38/5 (↑0.01 vs Oct 2026) The average rating of products in this category, based on all submitted ratings
  • Top Trending Product: Scale GenAI Platform (+3.96%) - Among all products in this category, Scale GenAI Platform recorded the largest rating increase compared to last month

Last updated: November 17, 2026

How Does G2 Rank Synthetic Data Tools Products?

Why You Can Trust G2's Software Rankings:

  • 30 Analysts and Data Experts
  • 500+ Authentic Reviews
  • 124+ Products
  • Unbiased Rankings

G2's software rankings are built on verified user reviews, rigorous moderation, and a consistent research methodology maintained by a team of analysts and data experts. Each product is measured using the same transparent criteria, with no paid placement or vendor influence. While reviews reflect real user experiences, which can be subjective, they offer valuable insight into how software performs in the hands of professionals. Together, these inputs power the G2 Score, a standardized way to compare tools within every category.

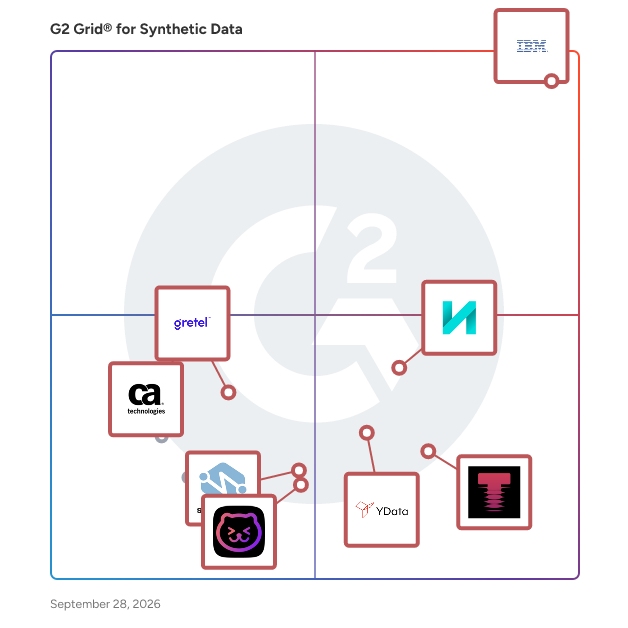
G2 Grid® for Synthetic Data Tools

G2 Grid® for Synthetic Data Tools plotting products by satisfaction and market presence

Highlighted products: IBM watsonx.ai, Tonic.ai, Tumult Analytics, YData, CA Test Data Manager, Gretel.ai, Syntheticus.ai | Synthetic Data Generator, and KopiKat.

Underlying data: [Grid® JSON](https://www.g2.com/categories/synthetic-data/grids.json?focus%5B%5D=ibm-watsonx-ai&focus%5B%5D=tonic-ai&focus%5B%5D=tumult-analytics&focus%5B%5D=ydata&focus%5B%5D=ca-test-data-manager&focus%5B%5D=gretel-ai&focus%5B%5D=syntheticus-ai-synthetic-data-generator&focus%5B%5D=kopikat)

Fincrimedynamics

FinCrime Dynamics specializes in enhancing financial institutions' defenses against financial crime and fraud through the use of synthetic data and simulation testing. By creating customized threat testing programs, they help organizations identify and address vulnerabilities in their systems before they can be exploited by real criminals. Their services are tailored to various sectors, including banks, payment companies, neo banks, crypto firms, foreign exchanges, and consultancies. Key Features and Functionality: - Financial Crime and Fraud Control Testing: Develops bespoke testing programs by understanding clients' business operations, systems, and potential threat exposures. - Simulation and Synthetic Data Solutions: Utilizes synthetic data and simulation techniques to safely uncover gaps and errors in controls. - Service and Product Offerings: Provides a range of services and products designed to effectively improve anti-financial crime and fraud controls, tailored to specific problems. - Industry Engagement: Collaborates with financial institutions, government agencies, and law enforcement to promote intelligence sharing and collective efforts against financial crime and fraud. Primary Value and Solutions Provided: FinCrime Dynamics empowers financial institutions to proactively combat financial crime and fraud by offering independent, expert-driven testing and optimization of their control systems. By leveraging synthetic data and simulations, they enable organizations to: - Simulate Financial Crime and Fraud: Test anti-financial crime and fraud controls in a safe environment using simulations of known and customized threat scenarios. - Secure Data Privacy: Mitigate data privacy concerns by using synthetic data that retains analytical qualities without tracing back to original sources. - Enhance Data Quality: Improve data quality by cleansing and reducing bias, with customized labeling for more effective testing. - Scale Data Generation: Quickly generate large amounts of data from small source datasets, avoiding the need for continual access to and cleansing of real data. Through these solutions, FinCrime Dynamics helps clients strengthen their defenses, reduce potential losses, and confidently grow their businesses while ensuring compliance with anti-financial crime regulations.

Who Is the Company Behind Fincrimedynamics?

Gan AI

Gan AI is an advanced artificial intelligence platform designed to generate realistic and high-quality synthetic media content. Leveraging Generative Adversarial Networks (GANs), it enables users to create images, videos, and audio that closely mimic real-world data. This technology is particularly beneficial for industries requiring large datasets for training machine learning models, content creation, and simulation purposes. Key Features and Functionality: - Synthetic Data Generation: Produces lifelike images, videos, and audio, facilitating the creation of diverse datasets without the need for real-world data collection. - Customizable Outputs: Allows users to tailor the generated content to specific requirements, ensuring relevance and applicability across various applications. - Scalability: Capable of generating large volumes of data efficiently, supporting extensive machine learning training and testing needs. - User-Friendly Interface: Provides an intuitive platform for users to easily generate and manage synthetic media content. Primary Value and User Solutions: Gan AI addresses the challenge of obtaining large, diverse, and high-quality datasets necessary for training robust machine learning models. By generating synthetic data, it reduces the dependency on real-world data collection, which can be time-consuming, expensive, and subject to privacy concerns. This solution accelerates the development and deployment of AI applications across various sectors, including healthcare, automotive, entertainment, and more.

Who Is the Company Behind Gan AI?

AI can help you find the answers. G2 helps you trust them.

Connect G2 to Claude or ChatGPT for answers grounded in G2's trusted reviews, comparisons, and pricing from real user insights.

How it works

GoMask.ai

GoMask.ai is an AI-powered test data management platform designed to streamline the creation of compliant and realistic test datasets. By integrating advanced data masking and synthetic data generation directly into development pipelines, GoMask.ai enables engineering teams to produce production-like test data in minutes, significantly reducing the time and risk associated with traditional test data provisioning. Key Features and Functionality: - Data Masking: Automatically identifies and replaces sensitive information in production data with realistic, fictitious values, preserving data format, structure, and referential integrity across tables. - Synthetic Data Generation: Creates entirely new datasets based on defined schemas and rules, producing statistically similar data to production while handling complex table relationships and custom business logic. - AI-Powered Data Discovery: Utilizes advanced AI to detect and classify sensitive data across databases, including personal identifiers, financial data, and healthcare information, ensuring comprehensive data protection. - Compliance Automation: Built-in frameworks ensure adherence to regulations such as GDPR, HIPAA, and PCI-DSS, with features like audit trail generation, policy enforcement, and regulatory reporting. - Integration and Scalability: Supports over 200 databases and integrates seamlessly with CI/CD pipelines, offering enterprise-grade security, performance monitoring, and scalability to handle large datasets efficiently. Primary Value and User Solutions: GoMask.ai addresses the critical challenge of test data bottlenecks that impede development velocity and pose compliance risks. By providing instant access to compliant, realistic test data, it eliminates the delays associated with manual data provisioning and the dangers of using production data in testing environments. This empowers development, QA, and DevOps teams to accelerate software delivery, ensure data privacy, and maintain regulatory compliance without compromising on data quality or security.

Who Is the Company Behind GoMask.ai?

Grably

Grably is a decentralized data ownership network (DeDON) that revolutionizes AI training by providing high-quality, user-consented datasets. By sourcing data directly from individuals, Grably ensures authenticity, diversity, and compliance with global privacy regulations, empowering AI developers with the precise data needed to build more accurate and efficient models. Key Features and Functionality: - Off-the-Shelf Datasets: Access a vast collection of pre-curated datasets across various domains, including multi-race facial recognition, before-and-after weight loss images, damaged car photos, X-rays, human body parts, indoor object segmentation, person home activity, and dashcam traffic scenes. - Custom Data Collection: Leverage Grably's platform to gather high-quality, user-consented data tailored to specific AI model requirements. - Data Curation and Annotation: Enhance datasets with curation services to ensure relevance and accuracy, and utilize expert annotation services to label data precisely, improving AI model training and performance. - Compliance and Security: All datasets adhere to global privacy regulations, including GDPR and CCPA, ensuring ethical sourcing and full transparency in data collection. Primary Value and Solutions Provided: Grably addresses the critical need for high-quality, diverse, and ethically sourced data in AI development. Traditional datasets often suffer from being outdated, biased, or collected without proper consent. Grably solves these issues by offering: - Authentic Data: Sourced directly from users with full consent, ensuring real-world applicability and reducing bias. - Enhanced Model Performance: Provides precise, industry-specific datasets that lead to faster, smarter, and more efficient AI models. - Ethical Data Practices: Ensures compliance with privacy regulations and offers transparency in data collection, fostering trust and integrity in AI development. By connecting AI developers with user-owned data, Grably empowers the creation of more accurate and responsible AI technologies.

Who Is the Company Behind Grably?

  • Seller: Grably
  • Year Founded: 2024
  • HQ Location: N/A
  • LinkedIn® Page: www.linkedin.com
    6 employees on LinkedIn®

GritRender

GritRender generates synthetic documents, images and audio with known values for development, QA and AI evaluation. Teams configure fields, business rules, volume and controlled variations to build repeatable test sets for OCR, document extraction and other enterprise workflows. Visual variants can include low light, blur, fax and photocopy conditions so teams can evaluate difficult cases against expected results. GritRender can be used independently or alongside GritRedact to expand coverage from approved, reviewed source content. It is available as a fully offline on-premises deployment or a sales-assisted SaaS subscription, through a web platform and customer APIs after onboarding. Start with the document types, required fields, business rules and failure cases your team needs to test.

Who Is the Company Behind GritRender?

Hazy

Hazy is an enterprise-grade synthetic data platform designed to generate high-quality, privacy-compliant synthetic data that mirrors the statistical properties and relationships of original datasets. This enables organizations to utilize data for analytics, machine learning, and testing without exposing sensitive information. Key Features and Functionality: - Data Privacy and Security: Hazy ensures that sensitive data remains within the organization's environment, eliminating the need for data to leave its secure infrastructure. - High-Quality Synthetic Data Generation: The platform produces synthetic data that preserves the statistical characteristics and referential integrity of the original data, ensuring its utility for various applications. - Scalable Deployment Options: Hazy offers flexible deployment methods, including self-hosted options and integration with cloud services like AWS, allowing organizations to scale their synthetic data capabilities efficiently. - User-Friendly Interface: With a no-code interface, Hazy enables both technical and non-technical users to generate synthetic data quickly and easily. - Advanced Automation: The platform features enhanced and automated datatype detection, reducing manual configuration efforts and minimizing the risk of errors. Primary Value and Problem Solved: Hazy addresses the critical challenge of utilizing sensitive data while maintaining privacy and compliance with regulations. By generating realistic synthetic data, organizations can accelerate data-driven projects, enhance machine learning models, and conduct thorough testing without compromising data security. This approach not only safeguards sensitive information but also streamlines data access and collaboration across teams, fostering innovation and efficiency.

Who Is the Company Behind Hazy?

Husool

Effortlessly retrieve diverse datasets and generate high-quality synthetic data. Whether you need data for banking, finance, sciences, insurance, ERP, CRM, healthcare, retail, or sales, Husool covers it all, ensuring the highest standards of data privacy and compliance.

Who Is the Company Behind Husool?

InsightDataGen

InsightDataGen is an AI-powered platform designed to generate realistic, privacy-compliant synthetic data across various formats, including structured databases, documents, and streaming pipelines. By simulating real-world data patterns, it accelerates development, testing, and data science workflows without compromising sensitive information. Key Features and Functionality: - Schema Definition: Import or create data schemas with business rules, referential integrity, and value constraints. - AI-Driven Data Generation: Utilize algorithms to produce statistically accurate data that maintains patterns and relationships across columns and tables. - Validation and Transformation: Implement automated validation to ensure data quality and compliance, with options for custom business logic transformations. - Flexible Data Export: Deliver generated data to various destinations, including files, databases, APIs, S3 buckets, or Kafka pipelines. - Support for Multiple Data Formats: Generate data in formats such as CSV, JSON, XML, SQL, Parquet, PDF, DOCX, XLSX, HTML, TXT, and streaming protocols like Kafka, Avro, Protobuf, WebSocket, and MQTT. Primary Value and User Solutions: InsightDataGen addresses the challenge of obtaining diverse and realistic test data without exposing sensitive information. It enables development teams to populate databases instantly, test edge cases, and create load-testing datasets. QA and testing teams can generate comprehensive test data for automation and simulate production-like volumes. Data scientists benefit from large-scale training datasets and the ability to simulate rare events. Additionally, the platform ensures compliance with data privacy regulations like GDPR and HIPAA, allowing organizations to share data safely and meet regulatory requirements.

Who Is the Company Behind InsightDataGen?

K2view Synthetic Data Generation

K2view Synthetic Data Generation is a software solution that enables organizations to create realistic, compliant datasets for testing, analytics, and AI use cases without exposing sensitive information. It supports multiple generation methods, including AI-based generation, rules-based logic, and data cloning, allowing users to match data generation techniques to specific requirements. The platform manages the full lifecycle of synthetic data, from data preparation and generation to provisioning and maintenance. It can generate data with or without access to production sources, making it suitable for both privacy-sensitive and greenfield scenarios. Generated data preserves relationships and structure across systems, ensuring it behaves similarly to production data in downstream environments. Synthetic data can be provisioned on demand into development, testing, and analytics environments, and integrated into CI/CD workflows to support automated pipelines. The platform also includes capabilities for data versioning, reservation, rollback, and aging. Key capabilities include: • Multi-method synthetic data generation (AI, rules-based, and cloning) • Preservation of referential integrity and cross-system relationships • Self-service data generation and provisioning for technical and non-technical users • Lifecycle management including versioning, rollback, and data aging • Integration with CI/CD pipelines and enterprise data environments

Who Is the Company Behind K2view Synthetic Data Generation?

  • Seller: K2View
  • Year Founded: 2009
  • HQ Location: Dallas, TX
  • LinkedIn® Page: www.linkedin.com
    187 employees on LinkedIn®

MediWoRx Synthetic Data

MediWoRx Synthetic Data offers high-fidelity, clinician-validated synthetic healthcare datasets designed to mirror authentic patient encounters without utilizing real patient records. These datasets are crafted to support the development of medical AI applications, ensuring both safety and compliance by containing zero protected health information (PHI) and adhering to HIPAA standards. Each dataset undergoes rigorous quality checks, including reviews by experienced nurse practitioners and physicians, to maintain clinical accuracy and reliability. Key Features and Functionality: - Clinical AI Training: Provides realistic longitudinal patient data and treatment responses for training AI models. - EHR System Testing: Facilitates testing of electronic health record systems with complex patient histories and continuity. - Disease Progression Research: Enables the study of disease progression through authentic patient journeys. - Medical Education: Creates realistic clinical scenarios for training and educational purposes. - True Longitudinal Continuity: Ensures patient journeys reflect proper continuity, treatment responses, and disease progression. - Zero PHI, Full Fidelity: Generates data from expert-designed prompts and medically verified logic, ensuring compliance and data integrity. - Clinician in the Loop: Incorporates reviews by experienced healthcare professionals to validate data quality. - Training Data Ready: Offers structured schema, metadata tracking, quality control validation, and multiple export formats for seamless AI model training. - Plug-and-Play Formats: Provides datasets in CSV, JSONL, and FHIR-structured formats for easy integration. - Regulatory Peace of Mind: Exceeds HIPAA and 42 CFR Part 2 privacy standards, ensuring compliance and security. Primary Value and User Solutions: MediWoRx addresses the critical need for high-quality, privacy-compliant healthcare data in AI development and research. By offering synthetic datasets that replicate real-world clinical scenarios without exposing actual patient information, MediWoRx enables organizations to: - Accelerate AI Development: Train and validate AI models with realistic data, reducing the time and resources required for data collection and preparation. - Ensure Compliance: Utilize datasets that are free from PHI, mitigating legal and ethical concerns associated with patient data usage. - Enhance System Testing: Test and refine electronic health record systems and other healthcare applications using complex, lifelike patient data. - Advance Medical Research: Conduct disease progression studies and other research initiatives with data that accurately reflects patient journeys. - Improve Medical Education: Develop realistic training scenarios for medical professionals, enhancing learning outcomes and preparedness. By providing these comprehensive, ready-to-use datasets, MediWoRx empowers healthcare organizations, researchers, and educators to innovate and improve patient care while maintaining the highest standards of data privacy and compliance.

Who Is the Company Behind MediWoRx Synthetic Data?

Mindtech

Mindtech, now integrated into Synthera's Chameleon™ platform, offers a comprehensive solution for generating unlimited, high-quality synthetic data tailored for computer vision projects. This integration empowers machine learning engineers, product owners, and AI teams to rapidly create diverse datasets, enhancing the training and robustness of AI models across various industries. Key Features and Functionality: - Unlimited Data Generation: Chameleon™ provides the capability to produce an unlimited amount of synthetic data, facilitating extensive training and testing of computer vision models. - Advanced Simulation Tools: The platform includes a behavioral simulator that accurately replicates real-world scenarios, ensuring the generated data is relevant and effective for AI training. - Diverse Digital Humans: Chameleon™ features unique digital human models with unlimited variations, promoting the development of unbiased and robust AI systems. - Multi-Camera Support: The platform supports synchronized outputs from up to 100 simultaneous cameras, providing high-resolution, high-fidelity data for comprehensive model training. - Comprehensive Annotations: Chameleon™ offers advanced annotations in an open format, facilitating both machine and human readability, and supporting various AI applications. Primary Value and Problem Solved: By integrating Mindtech's technology into Chameleon™, Synthera addresses the challenges associated with acquiring diverse and extensive datasets for AI training. Traditional data collection methods are often time-consuming, costly, and may raise privacy concerns. Chameleon™ overcomes these obstacles by enabling rapid, cost-effective generation of synthetic data that mirrors real-world conditions. This approach accelerates the development and deployment of accurate, robust computer vision systems, reducing development costs and timeframes, and ensuring compliance with ethical and legal standards.

Who Is the Company Behind Mindtech?

Bijou Barry
BB
Researched and written by Bijou Barry