Stockmark
Who Is the Company Behind Stockmark?
- Seller: Stockmark
- Year Founded: 2016
- HQ Location: 港区, JP
-
LinkedIn® Page: www.linkedin.com
121 employees on LinkedIn®
Total Products under this Category: 298
Last updated: November 01, 2026
Why You Can Trust G2's Software Rankings:
G2's software rankings are built on verified user reviews, rigorous moderation, and a consistent research methodology maintained by a team of analysts and data experts. Each product is measured using the same transparent criteria, with no paid placement or vendor influence. While reviews reflect real user experiences, which can be subjective, they offer valuable insight into how software performs in the hands of professionals. Together, these inputs power the G2 Score, a standardized way to compare tools within every category.
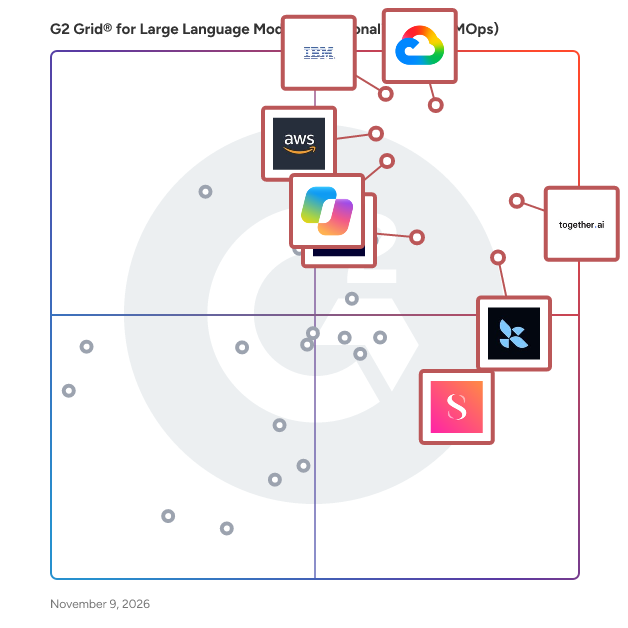
Highlighted products: Gemini platform, Together.ai, IBM watsonx.ai, AWS Bedrock, Langchain, Microsoft Copilot, AutoGPT, and SuperAnnotate.
Underlying data: [Grid® JSON](https://www.g2.com/categories/large-language-model-operationalization-llmops/grids.json?focus%5B%5D=gemini-platform&focus%5B%5D=together-ai&focus%5B%5D=ibm-watsonx-ai&focus%5B%5D=aws-bedrock&focus%5B%5D=langchain&focus%5B%5D=microsoft-copilot-2026-08-27&focus%5B%5D=autogpt&focus%5B%5D=superannotate)
SubQ is an advanced large language model (LLM) designed to handle extensive context lengths, enabling reasoning over millions of tokens in a single prompt. This capability allows users to process entire codebases, comprehensive document collections, and long-running agent states without compromising quality. Built on a fully sub-quadratic sparse-attention architecture, SubQ efficiently manages large-scale data processing tasks that traditional models struggle with. Key Features and Functionality: - Extended Context Window: Supports up to 12 million tokens, facilitating comprehensive analysis of extensive datasets. - Efficient Processing: Utilizes a sub-quadratic sparse-attention mechanism, reducing attention computation by nearly 1,000 times compared to traditional models, resulting in faster processing and lower costs. - High Retrieval Accuracy: Achieves near-perfect performance on long-context retrieval tasks, including single-fact and multi-task retrievals. - Versatile Integration: Offers an API for developers and enterprise teams, as well as a specialized tool for coding agents, enabling seamless incorporation into various workflows. Primary Value and User Solutions: SubQ addresses the limitations of existing LLMs in handling extensive context lengths by providing a scalable and efficient solution. It empowers users to perform in-depth analyses of large datasets, such as entire code repositories or comprehensive document collections, in a single pass. This capability enhances productivity, reduces processing time, and lowers operational costs, making it an invaluable tool for developers, researchers, and enterprises dealing with complex and voluminous information.
Connect G2 to Claude or ChatGPT for answers grounded in G2's trusted reviews, comparisons, and pricing from real user insights.
Supermemory is a universal memory API designed to enhance AI applications by providing persistent, long-term memory capabilities. It addresses the common limitation of AI models forgetting context between interactions, enabling them to recall relevant information from previous conversations, files, and tools. This ensures that AI responses remain consistent, contextual, and personalized over time. Key Features and Functionality: - Universal Memory Layer: Supermemory serves as a universal memory layer that enables Large Language Models (LLMs) to maintain persistent context and memories across different applications and sessions. - Developer-Friendly API: Supermemory provides a simple, affordable solution that eliminates months of technical complexity, allowing developers to focus on shipping their product without building infrastructure. - Multi-Modal Support: Supermemory is natively multi-modal and can automatically detect the content type of the document you are adding, using the best tools to extract content from URLs and process it for optimal memory storage. - Scalable and Fast: Supermemory retrieves memories in milliseconds, up to 10× faster than Zep and 25× faster than Mem0. Primary Value and User Solutions: Supermemory solves the fundamental limitation of AI forgetting everything between conversations by providing a universal memory layer that enables LLMs to maintain persistent context and memories across different applications and sessions. This ensures that AI assistants remember who you are, what you've discussed, and what matters to you, creating a persistent, personalized experience that grows smarter with every interaction.
Tasq.ai – The Production-First AI Data Optimization Platform 95% of AI models lose accuracy within 6 months of deployment due to data drift and edge cases. Real-world edge cases, data drift, and unlabeled anomalies introduce blind spots that degrade performance over time. Most platforms stop at training data, leaving production environments without the tools to maintain or improve model precision. Tasq.ai fills this critical gap. It is the only platform purpose-built to optimize AI systems in production, maintaining +95% model accuracy in production. Through continuous enrichment loops, Tasq.ai identifies data quality issues in real-time, routes them through hybrid workflows combining AI and human expertise, and feeds corrected data back into the live pipeline. This reduces manual data correction by 80%, keeps models sharp, accurate, and responsive to changing conditions. Trusted by +30 enterprise teams processing over 1B data points across Fortune 500 companies. Core Differentiators: * Live Production Optimization Detects and resolves data issues in real-time to prevent model decay * Enrichment Loops Creates closed feedback cycles that improve data quality continuously * Hybrid AI + Human Workflows Distributes tasks intelligently across ML models and global experts * Business-Level Visibility Tracks ROI, accuracy trends, and operational KPIs * Multi-Modal, Elastic Processing Handles text, image, video, and audio with scalable infrastructure * Seamless MLOps Integration Easily connects to existing systems with minimal setup Best Fit For: E-commerce teams refining catalog accuracy, content platforms maintaining moderation quality, robotic companies improving perception systems and edge-case handling, and retailers matching products across complex formats Why Tasq.ai Works Better: * Compared to labeling tools: We optimize deployed models instead of just preparing training data and prevent costly model retraining cycles. * Compared to generic MLOps: We add built-in quality control through enrichment. * Compared to internal solutions: We offer faster implementation with enterprise-grade scale at better costs.
Team Reboott is a company dedicated to transforming workplace efficiency through the development of enterprise AI solutions. By automating repetitive tasks, their products enable businesses to focus on more strategic initiatives. Their proprietary large language models (LLMs) are tailored for B2B and enterprise environments, ensuring secure and seamless AI integration. These models adeptly handle unstructured documents, including PDFs, Excel files, emails, images, and PowerPoint presentations, standardizing them to automate various processes. Additionally, Team Reboott offers advanced AI models for optical character recognition (OCR), speech-to-text (STT), and translation, which can be flexibly integrated into existing corporate systems. Their platform supports multiple LLMs, such as ChatGPT, Claude, and Gemini, allowing for versatile AI applications within a single framework. Key Features and Functionality: - Proprietary LLMs: Custom-developed models designed for secure and efficient AI adoption in enterprise settings. - Unstructured Document Processing: Standardization and automation of diverse document formats, including PDFs, Excel, emails, images, and PowerPoint files. - Advanced AI Models: High-precision OCR, STT, and translation models that integrate seamlessly with corporate systems. - Multi-LLM Support: Compatibility with various LLMs like ChatGPT, Claude, and Gemini within a unified platform. Primary Value and User Solutions: Team Reboott's AI solutions significantly enhance operational efficiency by automating routine tasks, allowing businesses to concentrate on core activities. Their products, such as askyour.trade and askyour.work, streamline complex processes in trade and office environments, respectively. For instance, askyour.trade automates trade documentation, including the generation of quotes and invoices, delivery management, AI order dashboards, import cargo monitoring, one-click electronic stamping, and specialized trade translations. This comprehensive automation reduces manual workload, minimizes errors, and accelerates processing times, thereby boosting overall productivity and competitiveness.
Testmyprompt is an AI-driven platform designed to assist users in crafting, testing, and refining prompts for various AI models. It offers a user-friendly interface that allows individuals to experiment with different prompt structures, ensuring optimal performance and desired outcomes from AI interactions. By providing real-time feedback and analytics, Testmyprompt enables users to understand how slight modifications can impact AI responses, thereby enhancing the effectiveness of their prompts. Key Features and Functionality: - Prompt Testing: Allows users to input and test various prompts to observe AI model responses. - Real-Time Feedback: Provides immediate insights into how prompts influence AI behavior. - Analytics Dashboard: Offers detailed analytics to track prompt performance over time. - User-Friendly Interface: Designed for ease of use, catering to both beginners and experienced users. - Customization Options: Enables users to tailor prompts to specific use cases and desired outcomes. Primary Value and Solutions: Testmyprompt addresses the challenge of creating effective prompts for AI models, which is crucial for obtaining accurate and relevant responses. By offering a platform to test and refine prompts, it empowers users to enhance their interactions with AI, leading to improved efficiency and productivity in tasks that rely on AI-generated content. This is particularly beneficial for developers, content creators, and businesses seeking to leverage AI capabilities effectively.
Thalium is a Brain-as-a-Service platform that gives applications persistent memory, structured reasoning, and governance via a single API call.Most AI-powered applications are stateless — every call starts from scratch, with no memory of prior decisions, no domain context, and no audit trail. Thalium changes this by wrapping large language model compute in a full cognitive chain: intent classification, memory retrieval, confidence-gated reasoning, and an immutable audit log — all triggered by one API endpoint.How it works: Your application sends input and context to Thalium's /v1/brain/invoke endpoint Every input is classified against an 11-type intent taxonomy and routed through the appropriate reasoning path A structured reasoning chain drafts, challenges, and confidence-gates the output before it returns The result is written to a persistent institutional memory ring — so the Brain gets smarter with every call Key capabilities: Three-ring memory architecture — session, entity, and institutional rings, all addressable in constant time Confidence gating and Coverage Map — the Brain knows what it knows; outputs are blocked below your confidence threshold Proprietary intent classification — 11 intent types, each with different reasoning paths and confidence thresholds Immutable audit trail — every decision, memory write, and gate verdict is logged and versioned Configurable guardrails — domain constraints enforced before any artifact leaves the chain Complete tenant isolation — your data never trains Thalium's models Who uses it: Engineering teams building production AI features that need to compound in quality over time. Used across healthcare (patient history), legal (matter memory), financial services (credit assessment), and SaaS (user personalisation).Pricing: Free tier available (500 invocations/month, 1 Brain Instance). Paid plans from £29/month. Enterprise tier available with sovereign deployment and custom SLAs.
Toqan is an advanced AI assistant designed to enhance organizational productivity by automating tasks, generating insights, and facilitating seamless collaboration. By integrating over 20 powerful large language models, Toqan supports a wide array of functions, enabling teams to focus on strategic initiatives while it handles routine operations. Key Features and Functionality: - Content Creation: Assists in writing, brainstorming, and developing presentations. - Data Analysis: Generates SQL code, analyzes datasets, and visualizes results. - Code Assistance: Debugs, generates, refactors, and fixes code snippets. - Customer Support: Transcribes, translates, summarizes, and analyzes customer interactions. - Legal Document Processing: Compares contracts and summarizes clause differences. - Personalized Responses: Tailors outputs to individual preferences, including language and saved prompts. - Data Integration: Connects to company databases for rapid and relevant insights. - Security and Compliance: Adheres to SOC II and ISO 27001 standards, ensuring data privacy. - Multi-Platform Availability: Accessible via web interface and Slack integration. Primary Value and Solutions Provided: Toqan empowers organizations by streamlining daily operations, reducing manual workload, and accelerating project timelines. Its ability to connect with internal company data ensures that teams have quick access to pertinent information, facilitating informed decision-making. By offering personalized responses and adhering to stringent security protocols, Toqan enhances user experience while maintaining data integrity. Ultimately, Toqan enables businesses to focus on high-impact tasks, fostering innovation and growth.
Tracea is an open-source observability and team memory platform designed for AI agents. It enables users to trace every large language model (LLM) call, tool execution, cost spike, error, and decision path, transforming completed sessions into a searchable team knowledge base. By running entirely on the user's infrastructure, Tracea ensures complete data ownership and eliminates vendor lock-in. Its deployment is straightforward, requiring only a two-minute setup, and it integrates seamlessly with various agent platforms without the need for wrappers or SDKs. Key Features and Functionality: - Session Tracking: Captures every LLM call, tool execution, error, and lifecycle event through transport-level interception, eliminating the need for additional wrappers or SDKs. - Real-time Dashboard: Provides insights into cost trends, token usage, session health, and agent performance, all displayed in a locally hosted React dashboard. - Issue Detection: Utilizes YAML-configurable rules to identify tool errors, high costs, rate limits, infinite loops, and empty responses, with hot-reload capabilities for immediate updates. - AI-Powered Root Cause Analysis (RCA): Offers root cause analysis using AI models like OpenAI, Anthropic, or Ollama, with the option to run entirely on-premises to maintain data privacy. - Alert Routing: Routes detected issues to Slack or any HTTP webhook, featuring per-destination rate limiting, deduplication, and exponential backoff retries. - Tracea Brain: Converts completed sessions into durable knowledge, preserving workflows, fixes, codebase notes, recurring failures, and decisions to prevent rediscovery. Primary Value and Problem Solved: Tracea addresses the critical need for comprehensive observability in AI agent operations by providing detailed tracing and analysis of agent activities. It empowers teams to understand the exact reasons behind agent failures, optimize performance, and manage costs effectively. By running entirely on the user's infrastructure, Tracea ensures data privacy and ownership, making it an ideal solution for organizations seeking to maintain control over their AI operations without relying on external cloud services.
TrainMyAI is a self-hosted knowledge base solution that enables organizations to interact with their proprietary content through a ChatGPT-style AI interface, accessible via web or private API. By implementing retrieval augmented generation (RAG), TrainMyAI ensures responses are grounded in trusted sources, mitigating common AI chatbot issues like hallucinations. Key Features and Functionality: - Multiple Knowledge Bases: Supports unlimited separate knowledge bases, each capable of handling up to 100,000 reference paragraphs (approximately 10-20 million words). - Comprehensive Content Management: Allows content addition via copy-paste, URLs, or file uploads (PDF, DOC, DOCX, TXT), with automatic paragraph extraction and semantic analysis. - User Management: Offers fine-grained permissions for user roles, including review, content management, and administration, with separate user management for each knowledge base. - Integration Capabilities: Provides a private JSON-RPC API for seamless integration into mobile or other applications, and supports WhatsApp integration for intuitive chatbot access. - Customization and Optimization: Features deep customization of AI parameters, HTML structure, and styles, along with AI-driven content optimization to enhance RAG results. - Usage Tracking and Analytics: Records all questions, responses, and references for later review, providing insights into user interactions and content effectiveness. Primary Value and User Solutions: TrainMyAI empowers organizations to maintain full control over their customized AI models, whether deployed on-premise or in the cloud. By enabling natural language queries of proprietary content, it enhances information accessibility and decision-making processes. The platform's robust user management, integration options, and customization capabilities ensure it meets diverse organizational needs, while its focus on data privacy and security addresses critical concerns in AI deployment.
