CoHarmonify
Who Is the Company Behind CoHarmonify?
- Seller: CoHarmonify
- Year Founded: 2025
- HQ Location: N/A
-
LinkedIn® Page: www.linkedin.com
1 employees on LinkedIn®
Total Products under this Category: 272
Last updated: October 23, 2026
Why You Can Trust G2's Software Rankings:
G2's software rankings are built on verified user reviews, rigorous moderation, and a consistent research methodology maintained by a team of analysts and data experts. Each product is measured using the same transparent criteria, with no paid placement or vendor influence. While reviews reflect real user experiences, which can be subjective, they offer valuable insight into how software performs in the hands of professionals. Together, these inputs power the G2 Score, a standardized way to compare tools within every category.
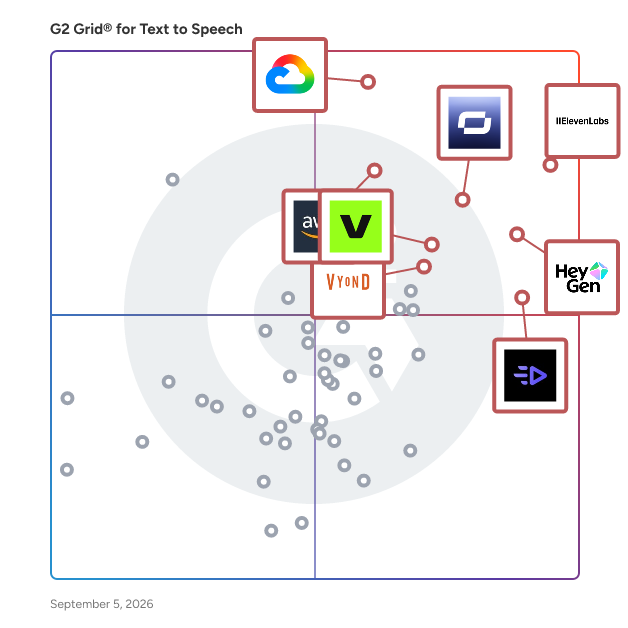
Highlighted products: ElevenLabs, Google Cloud Text-to-Speech, HeyGen, Synthesia, Creatify AI, Amazon Polly, VEED, and Vyond.
Underlying data: [Grid® JSON](https://www.g2.com/categories/text-to-speech/grids.json?focus%5B%5D=elevenlabsio&focus%5B%5D=google-cloud-text-to-speech&focus%5B%5D=heygen&focus%5B%5D=synthesia&focus%5B%5D=creatify-labs-inc-creatify-ai&focus%5B%5D=amazon-polly&focus%5B%5D=veed&focus%5B%5D=vyond)
Turn scripts into natural speech in seconds Type a line, pick a voice, and listen — free, no signup. English and Mandarin plus native Cantonese, Sichuanese, Shanghainese and Tianjin voices, and voice cloning from one short sample.
Connect G2 to Claude or ChatGPT for answers grounded in G2's trusted reviews, comparisons, and pricing from real user insights.
Deepdub is an AI-driven platform revolutionizing content localization by providing high-quality, emotionally resonant dubbing and voice-over services at scale. Utilizing proprietary emotive Text-to-Speech (eTTS™) technology, Deepdub enables creators to seamlessly translate and adapt their content for global audiences while preserving the original emotional intent and voice characteristics. Key Features and Functionality: - Emotive Text-to-Speech (eTTS™): Generates lifelike, emotionally adaptive speech that aligns with the context and sentiment of the content. - Voice Cloning: Creates digital replicas of voices, allowing for consistent and authentic multilingual dubbing. - Speech-to-Speech Translation: Instantly converts and translates voices, facilitating real-time multilingual communication. - Accent Control: Fine-tunes accents in over 130 languages to cater to diverse regional preferences. - Extensive Voice Library: Offers a vast collection of fully licensed, Hollywood-grade voices suitable for various applications. - Deepdub GO: A self-service professional AI dubbing studio that empowers teams to manage their dubbing projects efficiently. - Voice API for AI Agents: Integrates lifelike, emotionally adaptive speech into AI agents, enhancing user interactions. Primary Value and User Solutions: Deepdub addresses the challenges of content localization by providing a scalable, cost-effective solution that maintains the emotional depth and authenticity of the original material. By automating the dubbing process with advanced AI technologies, Deepdub significantly reduces turnaround times and production costs, enabling creators to reach global audiences more efficiently. This ensures that content resonates with viewers across different languages and cultures, enhancing engagement and expanding market reach.
Deepdub's Voice API is an enterprise-grade solution designed to bring AI agents to life with emotionally adaptive, humanlike speech. Leveraging Deepdub's proprietary Emotive Text-to-Speech (eTTS™) technology, the API delivers real-time, expressive voice generation that supports over 100 languages and dialects. This enables AI agents to engage users with natural, context-aware interactions, enhancing user experience across various applications. Key Features and Functionality: - Real-Time Latency (~250ms): Ensures instant responsiveness in live interactions with a Time-to-First-Audio under 250 milliseconds. - Emotive Text-to-Speech Technology: Generates speech that dynamically adjusts tone, pitch, and pacing to align with context and sentiment, allowing AI agents to express emotions such as empathy, authority, or enthusiasm. - Fully Licensed, Hollywood-Grade Voices: Provides access to thousands of broadcast-ready voices, fully licensed for commercial and branded use, ensuring compliance and brand consistency. - Unlimited Scalability: Built to handle high-concurrency workloads without artificial throttling or latency degradation, supporting seamless scalability for enterprise applications. - Extensive Customization: Offers fine-tuning capabilities for accent, tempo, pitch, and emotional intensity to match the AI agent's role, tone, or target audience. - Compliance-Ready Infrastructure: Meets industry standards with TPN Gold, SOC 2, and GDPR compliance, providing a secure and reliable solution for enterprise deployment. Primary Value and User Solutions: The Deepdub Voice API addresses the need for AI agents to communicate in a manner that is both natural and emotionally resonant, bridging the gap between artificial intelligence and human interaction. By providing real-time, expressive, and customizable voice capabilities, the API enhances user engagement and trust in AI-driven applications. Its scalability and compliance-ready infrastructure make it suitable for a wide range of industries, including customer support, healthcare, education, and media, enabling organizations to deploy lifelike AI agents that can interact with users across diverse languages and cultural contexts.
Echovox Studio is a comprehensive platform designed to streamline the creation, management, and distribution of audio content. It offers a suite of tools that cater to both novice and experienced audio producers, enabling them to produce high-quality audio projects efficiently. Key Features and Functionality: - Intuitive Audio Editing: Provides a user-friendly interface for editing audio tracks, including cutting, merging, and applying effects. - Multi-Track Support: Allows for the layering of multiple audio tracks, facilitating complex audio compositions. - Built-in Sound Library: Offers a diverse collection of royalty-free sounds and music to enhance projects. - Collaboration Tools: Enables multiple users to work on the same project simultaneously, promoting teamwork and efficiency. - Export Options: Supports various audio formats for exporting finished projects, ensuring compatibility across different platforms. Primary Value and User Solutions: Echovox Studio addresses the challenges of audio content creation by providing an all-in-one solution that simplifies the production process. Its intuitive design reduces the learning curve for beginners, while its advanced features meet the demands of professional audio producers. By integrating editing, collaboration, and resource tools into a single platform, Echovox Studio enhances productivity and creativity, allowing users to focus on crafting compelling audio content without the hassle of managing multiple software applications.
F5 TTS is a state-of-the-art, free online text-to-speech (TTS) solution that leverages advanced artificial intelligence to convert written text into natural and expressive speech. Utilizing sophisticated algorithms and deep learning models, F5 TTS delivers highly realistic voices across multiple languages and accents, making it an invaluable tool for enhancing content accessibility and engagement. Key Features: - High-Quality Synthesis: Produces speech with exceptional clarity, fluency, and expressiveness, closely mimicking human intonation and speech patterns. - Multilingual Support: Offers voice synthesis in a wide array of languages and accents, enabling users to reach a global audience with localized content. - Voice Cloning: Allows the creation of custom voices using minimal audio input, facilitating personalized and branded voice experiences. Primary Value and Solutions: F5 TTS addresses the need for accessible and engaging audio content by providing a free, high-quality text-to-speech service. It empowers users to bring their written content to life, improve accessibility for individuals with reading difficulties, and create immersive audio experiences across various applications, including e-learning, virtual assistants, and audiobook production. By offering an easy-to-use platform with robust features, F5 TTS enables users to enhance their content's reach and impact without incurring additional costs.
F5-TTS is an advanced AI-powered text-to-speech (TTS) synthesis tool designed to convert text into natural, expressive speech with remarkable precision and ease. Utilizing cutting-edge technologies like Flow Matching and Diffusion Transformer, F5-TTS offers zero-shot voice cloning, multi-language support, and emotion expression capabilities, making it a versatile solution for various applications. Key Features and Functionality: - Zero-Shot Voice Cloning: F5-TTS can replicate any voice using just a short audio sample, eliminating the need for extensive training data. - Multi-Language Support: The tool supports multiple languages, including English and Chinese, enabling seamless code-switching and catering to a global audience. - Emotion Expression and Speed Control: Users can adjust the emotional tone and speed of the generated speech, allowing for the creation of dynamic and expressive audio content. - Advanced AI Speech Synthesis: Leveraging state-of-the-art AI algorithms, F5-TTS produces natural-sounding speech with accurate intonation and clarity. - Real-Time Processing: With an inference real-time factor (RTF) of 0.15, F5-TTS offers efficient real-time speech generation, suitable for applications requiring immediate voice output. Primary Value and User Solutions: F5-TTS addresses the need for high-quality, customizable, and efficient text-to-speech solutions across various industries. Its zero-shot voice cloning allows for the rapid creation of personalized voiceovers without extensive training data, making it ideal for content creators, educators, and marketers. The multi-language support and emotion expression features enable the production of engaging and culturally relevant audio content, enhancing user experience and accessibility. Additionally, the tool's real-time processing capability ensures timely delivery of speech outputs, essential for applications like virtual assistants and interactive voice response systems.
FlowSpeech is a context-aware text to speech tool that converts text into human-like audio. It helps creators, marketers, educators, and product teams produce more expressive voice output with emotion control, pause control, and 30+ voices.
GeckoDub is an AI-powered video dubbing and localization platform designed for marketing teams, agencies, and content creators. It automatically translates, voice clones, and lip-syncs videos into multiple languages while preserving tone, emotion, and timing. With intuitive tools for single or bulk uploads, GeckoDub enables brands to quickly adapt video ads and campaigns for global audiences — reducing production time from days to minutes.
Average Rating: 5.0/5.0
Total Reviews: 2
AI-generated summary from verified user reviews
"Very good software, crazy good lipsync, my friend didnt notice the person is not real"
Rating: 5.0/5.0 stars
— Milan V.
"I successfully translated my video ads for various EU markets"
Rating: 5.0/5.0 stars
— Borut M.
GitPodcast is an AI-powered tool that transforms GitHub repositories into engaging audio podcasts, enabling developers and tech enthusiasts to quickly comprehend project structures and content through auditory summaries. By simply replacing 'hub' with 'podcast' in any GitHub URL, users can generate concise podcast summaries, available in approximately 5-minute basic versions or more detailed 10-minute in-depth versions. Leveraging OpenAI and Azure Speech technologies, GitPodcast delivers clear and accessible audio content, enhancing productivity and learning efficiency. Key Features: - Instant Podcast Generation: Convert any GitHub repository into a podcast within seconds, facilitating quick comprehension of project structures and content. - Customizable Podcast Length: Choose between approximately 5-minute basic versions or 10-minute in-depth versions to suit different preferences for repository exploration. - Easy URL Integration: Simply replace 'hub' with 'podcast' in any GitHub URL or paste the repository link on the website to generate the podcast. - Powered by Advanced AI: Utilizes OpenAI for content summarization and Azure Speech SDK for natural text-to-speech conversion. - Free and Open Source: Available at no cost with open-source code for self-hosting and customization. - API Access (Work in Progress): A public API is planned to allow integration with other tools and workflows. Primary Value: GitPodcast addresses the challenge of quickly understanding complex codebases by converting GitHub repositories into accessible audio summaries. This approach is particularly beneficial for developers and tech enthusiasts who prefer auditory learning or need to grasp project details efficiently without reading extensive documentation. By offering instant, customizable, and AI-driven podcast generation, GitPodcast enhances productivity, learning efficiency, and accessibility in software development.
GPT Reader is a free, AI-driven text-to-speech (TTS) application that leverages ChatGPT's advanced voices to transform written content into high-quality, natural-sounding speech. Designed for versatility, GPT Reader allows users to input text directly, upload documents, or explore various ideas, all while enjoying an immersive auditory experience. The application is equipped with user-friendly features such as dark and light modes, adjustable playback speeds, pause and resume functions, and a full-screen user interface, enhancing the overall usability and customization options. By offering premium TTS capabilities at no cost, GPT Reader aims to revolutionize the way users engage with textual content, making it more accessible and enjoyable. Key Features and Functionality: - ChatGPT-Powered Voices: Utilizes advanced AI voices for a natural and engaging listening experience. - Multiple Input Methods: Supports direct text input and document uploads for flexible content conversion. - User-Friendly Interface: Offers dark and light modes, adjustable playback speeds, and a full-screen option for personalized use. - Playback Controls: Includes pause and resume functions to manage listening sessions effectively. Primary Value and User Solutions: GPT Reader addresses the need for accessible and high-quality text-to-speech solutions by providing a free platform that converts written content into lifelike speech. This enhances content consumption for users who prefer auditory learning, have visual impairments, or seek a hands-free reading experience. By integrating advanced AI voices and customizable features, GPT Reader offers an unparalleled TTS experience, making information more accessible and engaging for a diverse user base.
Graphlogic Conversational AI Platform consists on: Robotic Process Automation (RPA) and Conversational AI for enterprises, leveraging state-of-the-art Natural Language Understanding (NLU) technology to create advanced chatbots, voicebots, Automatic Speech Recognition (ASR), Text-to-Speech (TTS) solutions, and Retrieval Augmented Generation (RAG) pipelines with Large Language Models (LLMs).
Average Rating: 5.0/5.0
Total Reviews: 1
AI-generated summary from verified user reviews
"Amazing technology that changed the game"
Rating: 5.0/5.0 stars
— Verified User in Computer Software
