Best Text to Speech Software - Page 14

How Many Text to Speech Software Products Does G2 Track?

Total Products under this Category: 272

Category Stats (Oct 2026)

  • Average Rating: 4.51/5 (↑0.02 vs Sep 2026) The average rating of products in this category, based on all submitted ratings
  • Top Trending Product: Artlist (+10.31%) - Among all products in this category, Artlist recorded the largest rating increase compared to last month

Last updated: October 23, 2026

How Does G2 Rank Text to Speech Software Products?

Why You Can Trust G2's Software Rankings:

  • 30 Analysts and Data Experts
  • 23,600+ Authentic Reviews
  • 272+ Products
  • Unbiased Rankings

G2's software rankings are built on verified user reviews, rigorous moderation, and a consistent research methodology maintained by a team of analysts and data experts. Each product is measured using the same transparent criteria, with no paid placement or vendor influence. While reviews reflect real user experiences, which can be subjective, they offer valuable insight into how software performs in the hands of professionals. Together, these inputs power the G2 Score, a standardized way to compare tools within every category.

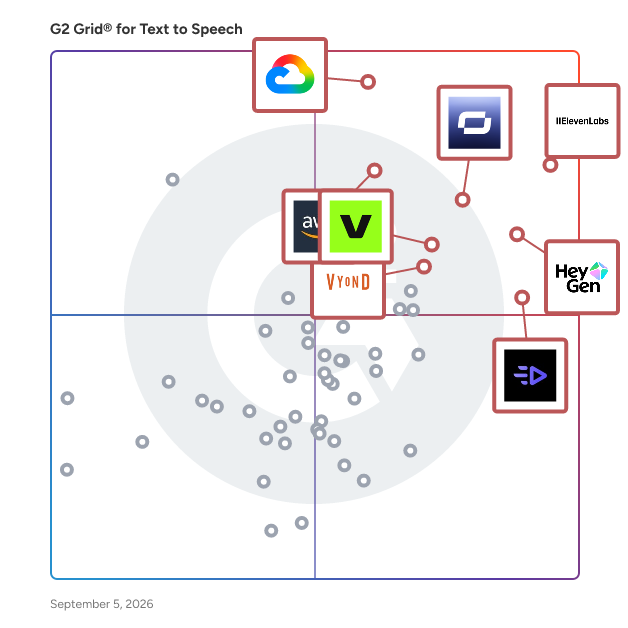
G2 Grid® for Text to Speech Software

G2 Grid® for Text to Speech Software plotting products by satisfaction and market presence

Highlighted products: ElevenLabs, Google Cloud Text-to-Speech, HeyGen, Synthesia, Creatify AI, Amazon Polly, VEED, and Vyond.

Underlying data: [Grid® JSON](https://www.g2.com/categories/text-to-speech/grids.json?focus%5B%5D=elevenlabsio&focus%5B%5D=google-cloud-text-to-speech&focus%5B%5D=heygen&focus%5B%5D=synthesia&focus%5B%5D=creatify-labs-inc-creatify-ai&focus%5B%5D=amazon-polly&focus%5B%5D=veed&focus%5B%5D=vyond)

ReadSpeaker TextAid

Who Is the Company Behind ReadSpeaker TextAid?

  • Seller: Readspeaker
  • Year Founded: 1999
  • HQ Location: Driebergen-Rijsenburg, Utrecht
  • Twitter: @ReadSpeaker
    1,870 Twitter followers
  • LinkedIn® Page: www.linkedin.com
    144 employees on LinkedIn®

Relaied

Relaied is an AI-driven podcast service that transforms academic papers, textbooks, and similar documents into engaging, discussion-based podcasts. By converting complex written materials into conversational audio formats, Relaied facilitates easier and more accessible learning experiences. Each podcast is complemented by a summary and a multiple-choice quiz to reinforce comprehension and retention. Key Features and Functionality: - Document Conversion: Users can upload their own documents or select from millions of available papers online to generate personalized podcasts. - Daily Podcasts: Subscribers receive a new podcast every day, tailored to the documents they've uploaded or chosen. - Comprehensive Learning Tools: Each podcast is accompanied by a summary and a quiz to enhance understanding and retention. - User-Friendly Interface: The platform is designed for ease of use, allowing users to sign up and start learning in just a few steps. Primary Value and User Solutions: Relaied democratizes learning by making high-quality educational content freely accessible. It addresses the challenge of digesting complex academic materials by converting them into engaging audio formats, enabling users to learn on the go. This approach breaks down barriers to knowledge, making continuous learning achievable for individuals regardless of their background or resources.

Who Is the Company Behind Relaied?

AI can help you find the answers. G2 helps you trust them.

Connect G2 to Claude or ChatGPT for answers grounded in G2's trusted reviews, comparisons, and pricing from real user insights.

How it works

ReplicaVox

ReplicaVox is an AI voice cloning platform that converts text into natural-sounding speech for publishers, businesses, and creators. Generate high-quality voiceovers, automate support calls, and scale audio content without hiring voice actors.

Who Is the Company Behind ReplicaVox?

Rime

Rime is a cutting-edge voice AI platform dedicated to transforming customer experiences through ultra-realistic, multilingual text-to-speech (TTS) models. By integrating advanced machine learning with deep linguistic insights, Rime delivers voices that breathe, laugh, and convey genuine human emotions, making interactions with AI agents indistinguishable from those with real people. Key Features and Functionality: - Arcana v2 TTS Model: Offers over 300 voices, including bilingual and multilingual options, with instant code-switching between English, Spanish, and Spanglish. Arcana v2 captures the warmth, rhythm, and subtle imperfections of real speech, ideal for applications requiring authenticity. - Mist v2 TTS Model: Delivers unmatched accuracy, speed, and customization at scale, with sub-200ms latency in the cloud and sub-100ms on-premises. Mist v2 is designed for high-volume, business-critical applications, offering extensive customization and streaming APIs. - Deployment Flexibility: Supports cloud, Virtual Private Cloud (VPC), and on-premises deployments, ensuring sub-100ms latency and compliance with industry standards such as HIPAA and SOC 2 Type II. - Developer-Friendly API: Provides easy integration with various audio formats (mp3, wav, pcm, mulaw) and supports features like pronunciation control, handling of brand names, currencies, lists, and more. Primary Value and Solutions: Rime addresses the challenge of creating engaging and authentic customer interactions by providing voice AI solutions that sound genuinely human. This realism builds trust and empathy, leading to improved customer satisfaction and business outcomes. For instance, businesses have reported a 15% increase in sales and a 75% decrease in call abandonment rates after implementing Rime's TTS models. By offering scalable, customizable, and compliant voice AI solutions, Rime empowers enterprises to enhance their customer engagement strategies effectively.

Who Is the Company Behind Rime?

  • Seller: Rime
  • HQ Location: San Francisco, US
  • Twitter: @rimelabs
    1,384 Twitter followers
  • LinkedIn® Page: www.linkedin.com
    18 employees on LinkedIn®

Rubidium

Rubidium is a speech recognition software that covers the entire scope of a voice dialogue system: input, output, and interaction.

Who Is the Company Behind Rubidium?

Samtts

Parler TTS is an advanced, lightweight text-to-speech model designed to generate high-quality, natural-sounding speech that mirrors the style of a specified speaker. Trained on 45,000 hours of narrated English audiobooks, it offers speaker consistency across generations with 34 characterized speakers that can be specified by name. Key Features and Functionality: - High-Fidelity Speech: Produces remarkably natural-sounding speech with exceptional audio quality and clarity. - Speaker Consistency: Maintains consistent speaker characteristics across multiple generations using 34 predefined speakers. - Controllable Features: Allows users to control gender, background noise, speaking rate, pitch, and reverberation through simple text prompts. - Optimized Inference: Supports SDPA, torch.compile, batching, and streaming for faster generation. - Fully Open-Source: All datasets, pre-processing, training code, and weights are publicly released under the Apache 2.0 license. - Fine-Tuning Support: Provides comprehensive documentation for training and fine-tuning custom Parler TTS models. Primary Value and User Solutions: Parler TTS addresses the need for high-quality, customizable text-to-speech solutions by offering a model that delivers natural-sounding speech with consistent speaker characteristics. Its open-source nature empowers developers and researchers to build upon and tailor the model to specific applications, enhancing accessibility and user engagement across various platforms.

Who Is the Company Behind Samtts?

Smartexam

SmartExam is an innovative AI-powered platform designed to revolutionize exam preparation for students and educators. By simply uploading study materials in formats such as PDF, DOCX, PPTX, or TXT, users can instantly generate interactive quizzes and engaging audio podcasts. This streamlined approach not only saves time but also enhances the learning experience by providing personalized and effective study tools. Key Features and Functionality: - AI-Generated Quizzes: Transform your study materials into comprehensive quizzes within seconds, allowing for efficient self-assessment and reinforcement of knowledge. - Audio Podcasts: Convert your documents into audio content, facilitating on-the-go learning and catering to auditory learners. - Multi-Language Support: Upload materials in any language and receive quizzes and podcasts in your preferred language, supporting over 45 languages. - Smart Analysis: The AI identifies key concepts and creates questions that effectively test your understanding, ensuring a thorough grasp of the material. - Personalized Learning: Tailor quizzes to your specific study materials and learning goals for maximum effectiveness. - Instant Feedback: Receive immediate explanations and corrections to enhance your comprehension and retention of the subject matter. Primary Value and Problem Solved: SmartExam addresses the common challenges of time-consuming and inefficient exam preparation by automating the creation of study aids. It empowers users to focus more on learning and understanding the content rather than spending excessive time on organizing study materials. By providing instant, personalized quizzes and podcasts, SmartExam enhances study efficiency, accommodates diverse learning styles, and ultimately improves academic performance.

Who Is the Company Behind Smartexam?

Sonofa

Sonofa is an innovative AI-powered tool designed to convert various forms of written content—such as webpages, PDFs, and images—into engaging, conversational podcasts. By leveraging advanced Large Language Models (LLMs) and state-of-the-art speech synthesis, Sonofa transforms traditional reading materials into dynamic audio experiences, making information consumption more accessible and enjoyable. Key Features and Functionality: - Content Transformation: Sonofa seamlessly converts diverse content formats, including web articles, academic papers, and images, into interactive audio narratives. - Conversational Audio Generation: Utilizing cutting-edge AI, Sonofa produces podcasts that mimic natural, human-like conversations, enhancing listener engagement and comprehension. - Podcast Integration: The generated audio content is accessible through private RSS feeds, allowing users to listen via their preferred podcast applications, such as Apple Podcasts or any RSS-compatible app. - Multilingual Support: Sonofa supports content in multiple languages, breaking down language barriers and broadening access to information. Primary Value and User Solutions: Sonofa addresses the challenge of information overload by enabling users to consume written content audibly, facilitating multitasking and improving information retention. It is particularly beneficial for individuals who prefer auditory learning, have visual impairments, or wish to stay informed during activities like commuting or exercising. By transforming static text into lively, conversational podcasts, Sonofa enhances the accessibility and enjoyment of learning and staying updated.

Who Is the Company Behind Sonofa?

Speechgen

SpeechGen is an advanced AI-powered text-to-speech (TTS) and speech-to-text (STT) platform designed to convert written text into natural-sounding speech and transcribe audio into text with high accuracy. Supporting over 1,000 voices across more than 150 languages, SpeechGen caters to a diverse range of users, including content creators, educators, marketers, and developers. Its intuitive interface allows users to generate professional-quality voiceovers and transcriptions efficiently, eliminating the need for expensive studio recordings or manual transcription services. Key Features and Functionality: - Extensive Voice and Language Support: Access to over 1,000 voices in more than 150 languages, enabling users to select the perfect voice and accent for their projects. - High-Quality Text-to-Speech Conversion: Utilizes advanced neural networks to produce realistic and human-like speech from text inputs. - Efficient Speech-to-Text Transcription: Quickly transcribes audio and video files into text with high accuracy, supporting various formats and providing features like speaker diarization and timestamping. - User-Friendly Interface: No installation required; users can access the platform directly through their web browser, making it convenient and accessible. - Flexible Export Options: Allows exporting of audio files in multiple formats (MP3, WAV) and transcriptions in formats like DOCX, TXT, and SRT, accommodating various workflow requirements. - Cost-Effective Pricing: Offers one-time payment options without monthly fees, providing flexibility and affordability for users with varying needs. Primary Value and Solutions Provided: SpeechGen addresses the need for efficient, high-quality, and cost-effective voiceover and transcription services. By leveraging AI technology, it enables users to create professional audio content and accurate transcriptions without the traditional expenses and time constraints associated with studio recordings and manual transcription. This empowers content creators, educators, marketers, and developers to enhance their projects with realistic voiceovers and precise transcriptions, improving audience engagement and accessibility.

Who Is the Company Behind Speechgen?

SpeechifyAI

SpeechifyAI is a text-to-speech and voice cloning API for developers. It gives engineering teams programmatic access to the speech models behind Speechify's own products, through a REST API, streaming endpoints, and official Python and TypeScript SDKs. Teams use it to put spoken audio inside software: article and document narration, audiobook and course production, accessibility features, IVR and support automation, in-product voiceover, and the speech layer inside conversational voice agents. Anywhere an application has to turn text into natural audio at scale, this is the layer that does it. Speed. The API streams audio instead of waiting for a full render, so playback starts while the rest of the sentence is still being generated. On the streaming model, Simba 3.2, first audio typically arrives in under 100 milliseconds: p50 56 ms and p90 102 ms, measured on production traffic on 15 September 2026. Third parties measure it independently too. Coval's public text-to-speech benchmark recorded a 109 ms median time to first audio on 20 September 2026. Voices and languages. More than 900 shared voices across 30+ languages and 35 locales, verified 10 September 2026. Voice cloning creates a custom voice from a short sample, with a consent workflow built into the API so teams can satisfy their own compliance requirements rather than building one. Cost. Pricing is per character with no per-seat fee, from $6 per million characters at volume, and a free tier of 500,000 characters so a team can evaluate the API before talking to anybody. Built for production, not demos. Streaming and batch modes, predictable latency under load, request logging, per-project spend limits and rate controls, and SDKs generated from the same specification as the API so they never drift from the documentation. Documentation, a quickstart and a free API key are at docs.speechify.ai. Every figure above carries the date it was measured; the docs hold the current numbers.

Who Is the Company Behind SpeechifyAI?

Bijou Barry
BB
Researched and written by Bijou Barry
Updated April 9, 2026