Best Text to Speech Software - Page 11

How Many Text to Speech Software Products Does G2 Track?

Total Products under this Category: 272

Category Stats (Oct 2026)

  • Average Rating: 4.51/5 (↑0.02 vs Sep 2026) The average rating of products in this category, based on all submitted ratings
  • Top Trending Product: Artlist (+10.31%) - Among all products in this category, Artlist recorded the largest rating increase compared to last month

Last updated: October 23, 2026

How Does G2 Rank Text to Speech Software Products?

Why You Can Trust G2's Software Rankings:

  • 30 Analysts and Data Experts
  • 23,600+ Authentic Reviews
  • 272+ Products
  • Unbiased Rankings

G2's software rankings are built on verified user reviews, rigorous moderation, and a consistent research methodology maintained by a team of analysts and data experts. Each product is measured using the same transparent criteria, with no paid placement or vendor influence. While reviews reflect real user experiences, which can be subjective, they offer valuable insight into how software performs in the hands of professionals. Together, these inputs power the G2 Score, a standardized way to compare tools within every category.

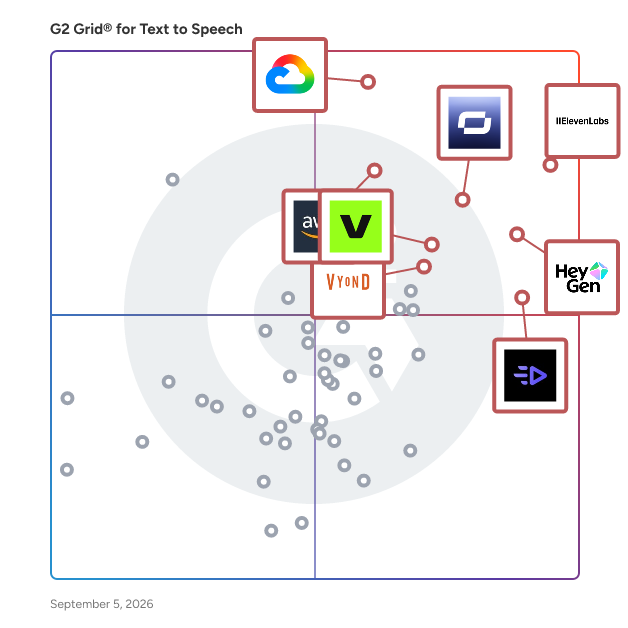
G2 Grid® for Text to Speech Software

G2 Grid® for Text to Speech Software plotting products by satisfaction and market presence

Highlighted products: ElevenLabs, Google Cloud Text-to-Speech, HeyGen, Synthesia, Creatify AI, Amazon Polly, VEED, and Vyond.

Underlying data: [Grid® JSON](https://www.g2.com/categories/text-to-speech/grids.json?focus%5B%5D=elevenlabsio&focus%5B%5D=google-cloud-text-to-speech&focus%5B%5D=heygen&focus%5B%5D=synthesia&focus%5B%5D=creatify-labs-inc-creatify-ai&focus%5B%5D=amazon-polly&focus%5B%5D=veed&focus%5B%5D=vyond)

Listnr

Listnr is an AI-powered text-to-speech (TTS) platform designed to convert written text into high-quality, natural-sounding audio. Leveraging advanced deep learning algorithms, Listnr offers over 570 unique voices across more than 75 languages, enabling users to create personalized voiceovers that cater to diverse audiences. Its intuitive interface allows for easy customization of speech elements such as pace, pauses, and pronunciations, ensuring the generated audio aligns perfectly with user preferences. Key Features and Functionality: - Extensive Voice Library: Access to over 570 distinct voices in 75+ languages, facilitating content creation for a global audience. - Advanced Customization: Adjust speech parameters including speed, pauses, and pronunciations to produce tailored audio outputs. - AI-Driven Realism: Utilizes deep learning to generate voices that closely mimic human speech patterns, enhancing listener engagement. - Versatile Applications: Suitable for various uses such as podcasting, educational materials, marketing content, and assistive technologies. - User-Friendly Interface: Simplifies the process of converting text to speech, making it accessible for users without technical expertise. Primary Value and User Solutions: Listnr addresses the need for efficient and cost-effective audio content creation by eliminating the complexities associated with traditional voiceover production. By providing a vast selection of customizable, lifelike voices, it empowers users to produce professional-grade audio without the need for recording equipment or voice talent. This capability is particularly beneficial for content creators, educators, and businesses aiming to enhance accessibility, reach a broader audience, and deliver engaging auditory experiences.

Who Is the Company Behind Listnr?

LMNT

LMNT is an advanced AI-driven text-to-speech (TTS) platform that delivers fast, lifelike, and affordable voice synthesis solutions. Designed to enhance user experiences across various applications, LMNT enables developers to integrate high-quality speech capabilities into their products with ease. Key Features and Functionality: - Studio-Quality Voice Cloning: Create precise voice replicas using just a 5-second audio sample, capturing nuances such as tone, speed, and inflections. - Multilingual Support: Generate speech in 24 languages, including Arabic, Chinese, English, French, German, Hindi, Japanese, and Spanish, with the ability to switch languages mid-sentence. - Low-Latency Streaming: Achieve real-time audio generation with latencies between 150-200 milliseconds, ideal for conversational applications, virtual agents, and gaming environments. - Flexible API Integration: Access a robust API with no concurrency or rate limits, supporting various programming languages and platforms for seamless integration. - Scalable Pricing Plans: Choose from multiple pricing tiers, including a free playground for experimentation and enterprise plans tailored to high-volume needs. Primary Value and User Solutions: LMNT addresses the growing demand for natural and responsive AI-generated speech by providing a platform that combines high-quality voice synthesis with rapid processing times. This empowers developers and businesses to create more engaging and accessible user experiences, whether through virtual assistants, educational tools, or interactive media. By offering multilingual support and easy voice cloning, LMNT enables personalized and inclusive communication solutions, enhancing user engagement and satisfaction.

Who Is the Company Behind LMNT?

  • Seller: LMNT
  • HQ Location: San Francisco Bay Area, US
  • LinkedIn® Page: www.linkedin.com
    1,279 employees on LinkedIn®

Lovevoice

Lovevoice is an advanced AI-powered voice generator that transforms text into natural, human-like speech. Supporting over 70 languages and nearly 300 voices, it caters to a diverse range of content creation needs, from videos and podcasts to audiobooks and presentations. With customizable voice settings, users can adjust speech rate, pitch, and volume to achieve the desired tone and style. The platform also offers file transcription capabilities, supporting formats like PDF, TXT, and DOC, and allows for the download of high-quality MP3 audio files. Lovevoice's efficient text-to-speech conversion ensures quick processing without compromising quality, making it an invaluable tool for content creators aiming to produce professional and engaging audio content. Key Features: - Multilingual Support: Access to over 70 languages and nearly 300 AI voices, enabling content creation for a global audience. - Customizable Voice Settings: Adjustable speech rate, pitch, and volume to tailor the audio output to specific preferences. - File Transcription: Supports multiple file formats, including PDF, TXT, and DOC, facilitating seamless text-to-speech conversion. - High-Quality Audio Output: Generates lifelike and natural AI voices, providing professional-grade audio suitable for various applications. - Efficient Processing: Rapid text-to-speech conversion without compromising on quality, enhancing productivity for users. Primary Value: Lovevoice addresses the challenge of creating high-quality, natural-sounding voiceovers by offering an AI-driven solution that is both efficient and versatile. It eliminates the need for professional voice actors, reducing production costs and time. By supporting a wide range of languages and providing customizable voice settings, Lovevoice empowers users to produce engaging and accessible audio content tailored to diverse audiences. This makes it an essential tool for content creators, educators, marketers, and businesses seeking to enhance their multimedia offerings.

Who Is the Company Behind Lovevoice?

AI can help you find the answers. G2 helps you trust them.

Connect G2 to Claude or ChatGPT for answers grounded in G2's trusted reviews, comparisons, and pricing from real user insights.

How it works

MainVox

MainVox is an enterprise-grade text-to-speech solution designed to meet the stringent requirements of businesses operating within the European Union. By offering EU data residency, MainVox ensures that all data processing and storage comply with local regulations, providing organizations with enhanced data security and legal certainty. The platform's corporate account architecture facilitates seamless integration into existing enterprise systems, enabling efficient management of voice profiles and user access. Additionally, MainVox's hybrid voice profiles deliver high-quality, natural-sounding speech synthesis, catering to diverse business applications. Key Features and Functionality: - EU Data Residency: All data is processed and stored within the European Union, ensuring compliance with local data protection laws. - Corporate Account Architecture: Designed for enterprise use, the platform supports scalable account management and integration with existing business systems. - Hybrid Voice Profiles: Offers a range of customizable voice options that produce natural and engaging speech outputs. Primary Value and User Solutions: MainVox addresses the critical need for secure and compliant text-to-speech services within the EU. By ensuring data residency and legal adherence, it mitigates regulatory risks for businesses. The platform's robust architecture and high-quality voice synthesis enhance user engagement and operational efficiency, making it an ideal choice for enterprises seeking reliable and compliant voice solutions.

Who Is the Company Behind MainVox?

MakeVoice.io

MakeVoice.io is a B2B AI voice generation platform powered by ElevenLabs' neural TTS technology. It lets users create professional voiceover recordings in many languages directly from their browser — no registration, no software installation.

Who Is the Company Behind MakeVoice.io?

  • Seller: OPTIMUM
  • Year Founded: 1996
  • HQ Location: Hyvinkää, FI
  • LinkedIn® Page: www.linkedin.com
    1 employees on LinkedIn®

Meldstem

Meldstem lets businesses create professional phone greetings in minutes: welcome messages, phone menus (IVR), on-hold announcements, closed messages and voicemail greetings. Type your text, pick a voice, and listen to the complete result for free before you pay. No account needed for the preview. Files are delivered in the exact audio format your phone system requires (µ-law, a-law, PCM WAV or MP3), with upload instructions for RingCentral, Nextiva, Vonage, 8x8, GoTo Connect, Grasshopper, Ooma, Microsoft Teams and 3CX. Every file includes machine-readable disclosure that the audio was generated with AI, in line with the EU AI Act. Pricing starts at $24 per greeting, with credit packs for teams that need more. On-hold music with a spoken message is also available.

Who Is the Company Behind Meldstem?

Microsoft TTS Downloader

Microsoft™ Text-to-Speech Downloader is a user-friendly tool that enables effortless conversion of text into natural-sounding speech using Microsoft's advanced text-to-speech service. Designed for simplicity, it allows users to generate and download high-quality audio files with just one click, eliminating the need for technical expertise or familiarity with Microsoft Azure Cloud Service. This tool is ideal for content creators, educators, and developers seeking an efficient solution for producing lifelike speech audio. Key Features and Functionality: - One-Click Audio Generation and Download: Quickly convert text into speech and download the audio file instantly. - Support for Multiple Languages and Voices: Access a diverse range of languages and voice options to suit various needs. - Customizable Speech Settings: Adjust speech style, speed, and pitch to achieve the desired audio output. - User-Friendly Interface: Navigate the tool effortlessly without requiring technical knowledge or experience with cloud services. - Flexible Pricing Plans: Choose between a free plan with limited downloads or a Pro plan offering unlimited access and priority support. Primary Value and User Solutions: Microsoft™ Text-to-Speech Downloader addresses the need for a straightforward and efficient method to create high-quality speech audio from text. By simplifying the process and removing technical barriers, it empowers users to produce professional-grade audio content for various applications, including e-learning materials, assistive technologies, game development, podcasts, and audiobooks. The tool's accessibility and ease of use make it a valuable resource for individuals and organizations aiming to enhance their content with natural-sounding speech.

Who Is the Company Behind Microsoft TTS Downloader?

MiniMax Audio

MiniMax Audio is an advanced AI-driven platform that revolutionizes audio content creation through its state-of-the-art Text-to-Speech (TTS) technology and voice cloning capabilities. Designed to deliver natural, fluent speech across multiple languages, MiniMax Audio empowers users to produce high-quality voiceovers for videos, podcasts, audiobooks, and more. Its extensive library of over 300 voices in 17 languages, coupled with customizable audio parameters, ensures a personalized and immersive auditory experience. Key Features and Functionality: - Advanced Text-to-Speech (TTS): Transforms text into natural, fluent speech, supporting multiple languages to cater to diverse needs. Users can adjust various audio parameters to achieve the desired voice effect. - Voice Cloning: Enables the creation of custom voice models with as little as 10 seconds of audio input, allowing for unique and personalized voice outputs. - Voice Isolator: Utilizes advanced noise reduction technology to isolate vocals from complex background noise, facilitating the replication of any voice with clarity. - Official Voice Library: Offers a vast collection of over 300 voices across 17 languages and multiple accents, covering a wide range of styles and age groups to meet various project requirements. Primary Value and User Solutions: MiniMax Audio addresses the growing demand for high-quality, customizable audio content by providing tools that streamline the voice generation process. Content creators can produce professional-grade voiceovers without the need for extensive resources or time-consuming recording sessions. Enterprises can enhance their brand voice in advertisements and automated services, while developers and researchers can integrate flexible APIs to develop voice-interaction applications efficiently. By offering multilingual support and advanced customization options, MiniMax Audio ensures that users can create engaging and authentic audio experiences tailored to their specific needs.

Who Is the Company Behind MiniMax Audio?

  • Seller: MiniMax
  • Year Founded: 2021
  • HQ Location: Singapore, SG
  • LinkedIn® Page: www.linkedin.com
    138 employees on LinkedIn®

Who Uses This Product?

  • Company Size: 100% Medium

MMAudio

MMAudio is an advanced AI-powered tool designed to transform video content into high-quality audio seamlessly. By leveraging cutting-edge artificial intelligence, it enables users to extract and generate natural-sounding audio from videos, enhancing the overall multimedia experience. Whether you're a content creator, educator, or business professional, MMAudio simplifies the process of audio synthesis, making your projects more engaging and accessible. Key Features and Functionality: - Video to Audio Conversion: Effortlessly convert video files into synchronized audio tracks, supporting popular formats like MP4, AVI, and MOV. - Text to Audio Synthesis: Generate natural-sounding audio from text inputs, allowing for the creation of voiceovers and narrations without the need for recording. - Multiple Effect Types: Access a range of effect types, including Basic, Advanced, and Timeline effects, to customize the audio output to your specific needs. - Fast Processing Speeds: Experience rapid processing times, with the ability to process 8-second videos in just 2 seconds, significantly outpacing traditional methods. - Advanced Audio-Video Synchronization: Utilize smart AI algorithms to ensure perfect synchronization between audio and video, delivering a professional-grade dubbing experience. - Support for Various Video Formats: Work with a wide array of video formats, including MP4, AVI, and MOV, providing flexibility for different project requirements. Primary Value and User Solutions: MMAudio addresses the challenge of creating high-quality audio content from video sources without the need for extensive manual editing or recording. It offers a streamlined solution for content creators, educators, and businesses to enhance their multimedia projects with professional-grade audio. By automating the audio extraction and generation process, MMAudio saves time and resources, allowing users to focus on content creation and delivery. Its user-friendly interface and rapid processing capabilities make it an invaluable tool for anyone looking to improve the auditory component of their video content.

Who Is the Company Behind MMAudio?

Murf Dub

Create high-quality dubbing in 28+ languages in a fraction of the time

Who Is the Company Behind Murf Dub?

  • Seller: Murf Inc.
  • Year Founded: 2020
  • HQ Location: Salt Lake City, US
  • Twitter: @MURFAISTUDIO
    4,022 Twitter followers
  • LinkedIn® Page: www.linkedin.com
    114 employees on LinkedIn®

MyEdit

MyEdit is a cutting-edge AI-powered online photo and audio editor that offers a comprehensive suite of tools to elevate your creative projects. With features like Image Enhancer, AI Image Generator, AI Headshot, AI Extender, and more, MyEdit online Photo Editor empowers you to transform your images with ease. Additionally, MyEdit provides users with online audio editing tools to elevate sound quality to a professional level. Effortlessly convert text to speech or speech to text, remove wind or background noise, modify voice, extract instrumentals, determine track BPM, trim audio, and much more. Designed with user-friendliness in mind, MyEdit delivers a seamless and efficient experience for users of all skill levels.

Average Rating: 4.0/5.0

Total Reviews: 1

How Do G2 Users Rate MyEdit?

  • Has the product been a good partner in doing business?: 8.3/10 (Category avg: 8.7/10)

Who Is the Company Behind MyEdit?

  • Seller: CyberLink
  • Year Founded: 1996
  • HQ Location: New Taipei City, Taiwan
  • Twitter: @CyberLink
    8,580 Twitter followers
  • LinkedIn® Page: www.linkedin.com
    734 employees on LinkedIn®
  • Ownership: TWSE: 5203

Who Uses This Product?

  • Company Size: 100% Small

What Are Recent G2 Reviews of MyEdit?

Narralize

Narralize is an AI-powered platform that transforms PDF documents into concise, natural-sounding audio summaries in multiple languages. By leveraging advanced text-to-speech technology, it enables users to convert written content into engaging audio formats, making information more accessible and consumable for a global audience. This service is particularly beneficial for professionals, educators, and content creators seeking to enhance the reach and impact of their documents. Key Features and Functionality: - PDF to Audio Summary: Effortlessly convert PDF documents into clear and concise audio summaries. - Multiple Languages: Generate summaries in various languages to cater to a diverse audience. - AI-Powered Summarization: Utilize cutting-edge AI to extract key points and create engaging summaries. - Flexible Credit System: Operate on a simple credit system with rollover for unused credits, ensuring cost-effective usage. - High-Quality Audio: Enjoy crisp, clear audio that sounds professionally recorded. - API Access: Integrate Narralize directly into your applications with the provided REST API. Primary Value and User Solutions: Narralize addresses the challenge of making extensive written content more accessible and engaging by converting it into audio summaries. This transformation allows users to consume information on-the-go, enhances comprehension through auditory learning, and breaks language barriers by offering multilingual support. By streamlining the process of content consumption, Narralize empowers users to efficiently absorb and share information across different platforms and audiences.

Who Is the Company Behind Narralize?

Bijou Barry
BB
Researched and written by Bijou Barry
Updated April 9, 2026