Humelo
Who Is the Company Behind Humelo?
- Seller: Humelo
- HQ Location: 서울, KR
-
LinkedIn® Page: www.linkedin.com
9 employees on LinkedIn®
Total Products under this Category: 272
Last updated: October 23, 2026
Why You Can Trust G2's Software Rankings:
G2's software rankings are built on verified user reviews, rigorous moderation, and a consistent research methodology maintained by a team of analysts and data experts. Each product is measured using the same transparent criteria, with no paid placement or vendor influence. While reviews reflect real user experiences, which can be subjective, they offer valuable insight into how software performs in the hands of professionals. Together, these inputs power the G2 Score, a standardized way to compare tools within every category.
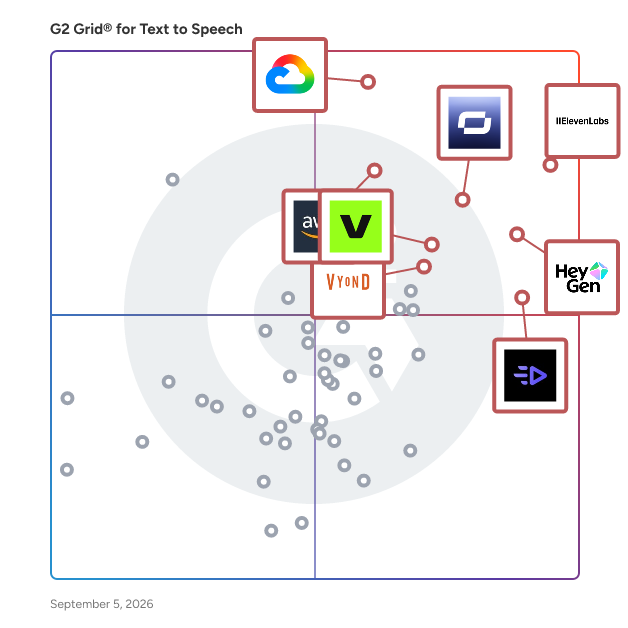
Highlighted products: ElevenLabs, Google Cloud Text-to-Speech, HeyGen, Synthesia, Creatify AI, Amazon Polly, VEED, and Vyond.
Underlying data: [Grid® JSON](https://www.g2.com/categories/text-to-speech/grids.json?focus%5B%5D=elevenlabsio&focus%5B%5D=google-cloud-text-to-speech&focus%5B%5D=heygen&focus%5B%5D=synthesia&focus%5B%5D=creatify-labs-inc-creatify-ai&focus%5B%5D=amazon-polly&focus%5B%5D=veed&focus%5B%5D=vyond)
Illuminate by Google is an experimental AI-powered tool designed to transform complex academic papers into accessible audio dialogues. By leveraging Google's advanced AI technologies, Illuminate enables users to engage with scholarly content through conversational audio, making intricate research more approachable and easier to comprehend. Key Features and Functionality: - AI-Powered Content Generation: Utilizes Google's Gemini AI model to process extensive academic texts, generating dialogues that discuss key points in a friendly and accurate exchange. - Flexible Input Options: Users can search for research papers of interest or provide links to one or multiple research papers, which the model then processes to create audio dialogues. - Customizable Audio Output: The system generates a dialogue script providing an overview of the paper(s) and discusses key insights, which is then rendered into a two-person voice conversation using AudioLM. Primary Value and User Solutions: Illuminate addresses the challenge of digesting complex academic material by converting it into engaging audio conversations. This approach caters to diverse learning preferences, allowing users to absorb information audibly, which can enhance comprehension and retention. By simplifying access to scholarly content, Illuminate supports continuous learning and makes advanced research more accessible to a broader audience.
IndexTTS2 is an open-source zero-shot text-to-speech (TTS) model capable of generating realistic human voices without the need for speaker-specific training data. It separates speaker identity from emotional tone, allowing you to fully control emotion, prosody, and timing for each utterance.
Connect G2 to Claude or ChatGPT for answers grounded in G2's trusted reviews, comparisons, and pricing from real user insights.
Inpodcast AI is an AI powered podcast studio for turning documents or text into podcasts, with script generation, editing, text to speech, and voice cloning. It supports uploading multiple files at once in PDF, Markdown, TXT, and DOCX formats. Users can choose input and output languages, with support for 76 languages, and generate scripts that match custom themes, character personalities, and outlines. It includes built in podcast formats such as monologue, two person conversation, interview, and roundtable, each producing a distinct style. The platform offers a voice library of 700 plus voices with multiple options per language. Voice cloning can work with as little as 10 seconds of audio and claims up to 99 percent similarity. The AI podcast editor lets users edit scripts, regenerate audio repeatedly, change speakers, switch voices and names, adjust playback speed for downloads, export scripts as Markdown, Text, or Word, publish and share podcasts, and automatically generate descriptions and cover images. Users can also create scripts from scratch and generate complete podcast audio files.
Instaread Player is a FREE embeddable article-to-audio conversion tool designed specifically for digital publishers, newsrooms, bloggers, and content creators. It allows website owners to instantly transform their written articles into high-quality, listenable audio. Core Functionality: Automated Article-to-Audio: When a publisher posts a new article, the Instaread tool automatically processes the text and generates an audio version in the background. Embeddable Widget: A clean, lightweight audio player is embedded directly at the top of the webpage. Website visitors simply click "play" to listen to the story instead of reading it. Key Features: Lifelike Text-to-Speech: The technology utilizes advanced voice clarity and natural pacing. It seamlessly handles complex text and inserts appropriate pauses at commas and periods, mimicking a real human narrator rather than a robotic text-to-speech system. Seamless Integration: It integrates easily into content management systems (including a dedicated WordPress plugin). There are no manual audio uploads or heavy scripts required by the website owner. Auto-Updating Audio: If a publisher edits or updates the text of an article after publishing, the Instaread Player intelligently detects the changes and automatically refreshes the audio track so listeners always get the most up-to-date version. Performance Optimized: The player widget is designed to be fast, mobile-friendly, and non-intrusive, blending naturally into a website’s theme without slowing down page load speeds. Benefits for Publishers: Increased Engagement & Accessibility: By offering an audio alternative, websites can meet the demands of multitaskers, commuters, and visually impaired users. This helps keep visitors engaged on the page for longer periods. New Revenue Streams: The player offers a built-in monetization model as well. Free Implementation: Publishers can utilize the technology and embed the player on their sites for free, covering the costs through the ad-supported model. Currently, the Instaread Player is utilized by local news outlets, health websites, and major digital publications (such as The Hill and DrAxe.com) to scale their web audio and offer a modern, podcast-like experience directly on their webpages.
Speech Recognition API is a mobile application that allows you to speak and translate words or phrases including emails or text in multiple languages.
Average Rating: 4.5/5.0
Total Reviews: 5
AI-generated summary from verified user reviews
"This helps you to create applications which require speech recognition."
Rating: 4.5/5.0 stars
— Ujjwal K.
"Tool for modern voice driven applications"
Rating: 4.5/5.0 stars
— Verified User in Automotive
Kitten TTS by KittenML is an advanced text-to-speech (TTS) solution designed to convert written text into natural-sounding speech. Utilizing cutting-edge machine learning algorithms, it delivers high-quality audio output that closely mimics human speech patterns and intonations. This technology is ideal for applications requiring realistic voice synthesis, such as virtual assistants, audiobooks, and accessibility tools. Key Features and Functionality: - Natural-Sounding Speech: Produces lifelike voice outputs that enhance user engagement and comprehension. - Multilingual Support: Offers a wide range of languages and dialects to cater to a global audience. - Customizable Voices: Allows users to select from various voice profiles or create custom voices to match specific brand identities. - Real-Time Processing: Provides swift text-to-speech conversion, suitable for applications needing immediate audio feedback. - Integration Capabilities: Easily integrates with existing systems and platforms through APIs, facilitating seamless deployment. Primary Value and User Solutions: Kitten TTS addresses the need for high-quality, natural-sounding voice synthesis in various applications. By offering realistic and customizable speech outputs, it enhances user experiences in virtual assistants, e-learning platforms, and content creation. Its multilingual support ensures accessibility for diverse audiences, while real-time processing meets the demands of interactive applications. The ease of integration allows businesses to implement the solution without significant infrastructure changes, making it a versatile tool for improving communication and engagement.
Kokoro TTS is an advanced AI text-to-speech model built on the StyleTTS 2 architecture, featuring 82 million parameters. It delivers high-quality, natural-sounding voice synthesis while maintaining a lightweight and resource-efficient design. Supporting multiple languages—including English, French, Korean, Japanese, and Mandarin—Kokoro TTS caters to diverse content needs, making it ideal for applications such as audiobooks, podcasts, training videos, and more. Its efficient architecture ensures scalability and exceptional audio quality, even with its compact size. Key Features and Functionality: - 82M Parameter Efficiency: Achieves exceptional speech synthesis quality with only 82 million parameters, enabling faster performance and reduced resource consumption. - Multilingual Support: Supports multiple languages, including American English, British English, French, Korean, Japanese, and Mandarin, allowing for diverse content creation. - Customizable Voicepacks: Offers multiple lifelike and stable voice options, enabling users to select specific tones or styles to suit their project's unique needs. - Automatic Content Segmentation: Features automatic chapter and section detection, simplifying the conversion of e-books and articles into well-organized audio. - OpenAI-Compatible Speech Endpoint: Seamlessly integrates with OpenAI APIs, providing developers and content creators the ability to extend its functionality across various applications. - Real-Time Audio Generation: Designed for ultra-fast audio generation, powered by NVIDIA GPU acceleration, ensuring smooth, high-quality audio synthesis without delays. Primary Value and User Solutions: Kokoro TTS addresses the need for efficient, high-quality, and natural-sounding text-to-speech solutions across various industries. Its lightweight design and multilingual capabilities make it an invaluable tool for: - Audiobook Creation: Easily transform e-book libraries into high-quality audiobooks, even for niche titles, with natural-sounding multilingual voices. - Training Materials and Tutorials: Generate clear and natural-sounding voiceovers in multiple languages, saving time and resources in content creation. - Enhancing Digital Content Accessibility: Convert written content into speech, aiding accessibility for visually impaired individuals and catering to audiences who prefer listening over reading. By offering a scalable, efficient, and versatile text-to-speech solution, Kokoro TTS empowers users to create diverse and accessible audio content with ease.
Kugel TTS is an EU-sovereign AI voice and speech synthesis platform designed for enterprises that require GDPR compliance, data residency, and sub-100ms latency. Our text-to-speech technology supports 30+ languages with exceptional handling of German, French, Italian, and multilingual edge cases. Built for regulated industries (banking, insurance, healthcare, telco), Kugel provides AI voice cloning, AI narration, and voice-to-text capabilities without US subprocessors. On-premises deployment via Kubernetes ensures complete data control.
Kvad is building Norwegian text-to-speech technology with a clear focus on making synthetic speech sound genuinely Norwegian. Unlike general-purpose multilingual TTS platforms, Kvad focuses specifically on the Norwegian language. Our technology is designed around the details that make speech sound natural to native listeners, including pronunciation, rhythm, prosody and natural speech patterns. Kvad enables developers and businesses to generate high-quality Norwegian speech for applications such as conversational AI, voice assistants, customer service, media, accessibility and other voice-based products. By specializing deeply in Norwegian rather than supporting hundreds of languages, our goal is to deliver more natural and authentic Norwegian voices and build the speech technology infrastructure for Norwegian AI.
Labs AI: Text to Speech is software that converts written content into natural-sounding audio using AI. It offers over 100 voices with tonal options like neutral, warm, and meditative, supports 50+ languages, and includes accents such as British, American, and Australian. Voice themes like narrator and podcast host help match tone to content. A standout feature is voice cloning, enabling personalized voice creation from a brief sample, with unlimited audio generation in that voice. The platform delivers studio-quality audio in seconds, eliminating the need for recording equipment or expertise, making it an all-in-one tool for creating spoken content.
