Best Text to Speech Software - Page 16

How Many Text to Speech Software Products Does G2 Track?

Total Products under this Category: 272

Category Stats (Oct 2026)

  • Average Rating: 4.51/5 (↑0.02 vs Sep 2026) The average rating of products in this category, based on all submitted ratings
  • Top Trending Product: Artlist (+10.31%) - Among all products in this category, Artlist recorded the largest rating increase compared to last month

Last updated: October 23, 2026

How Does G2 Rank Text to Speech Software Products?

Why You Can Trust G2's Software Rankings:

  • 30 Analysts and Data Experts
  • 23,600+ Authentic Reviews
  • 272+ Products
  • Unbiased Rankings

G2's software rankings are built on verified user reviews, rigorous moderation, and a consistent research methodology maintained by a team of analysts and data experts. Each product is measured using the same transparent criteria, with no paid placement or vendor influence. While reviews reflect real user experiences, which can be subjective, they offer valuable insight into how software performs in the hands of professionals. Together, these inputs power the G2 Score, a standardized way to compare tools within every category.

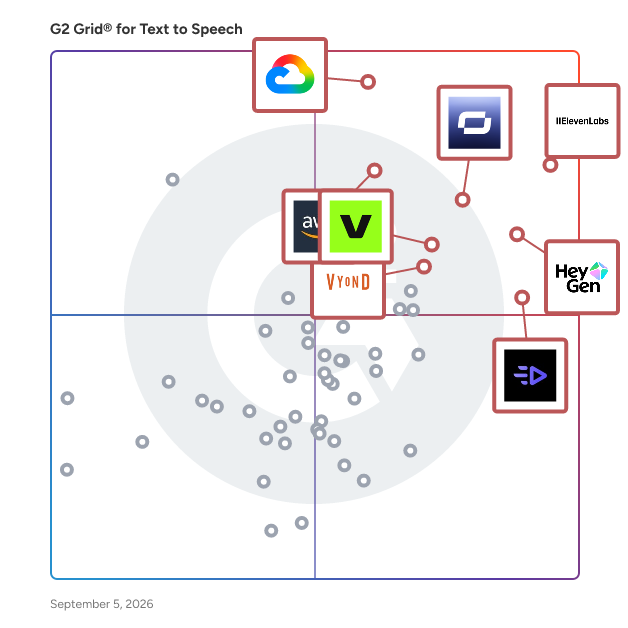
G2 Grid® for Text to Speech Software

G2 Grid® for Text to Speech Software plotting products by satisfaction and market presence

Highlighted products: ElevenLabs, Google Cloud Text-to-Speech, HeyGen, Synthesia, Creatify AI, Amazon Polly, VEED, and Vyond.

Underlying data: [Grid® JSON](https://www.g2.com/categories/text-to-speech/grids.json?focus%5B%5D=elevenlabsio&focus%5B%5D=google-cloud-text-to-speech&focus%5B%5D=heygen&focus%5B%5D=synthesia&focus%5B%5D=creatify-labs-inc-creatify-ai&focus%5B%5D=amazon-polly&focus%5B%5D=veed&focus%5B%5D=vyond)

Text to Speech.im

Text to Speech.im is an advanced online tool that leverages artificial intelligence to convert written text into natural-sounding speech. Designed to enhance accessibility and streamline content creation, it supports multiple languages and offers a diverse range of voice styles. Users can effortlessly generate high-quality audio files, making it an invaluable resource for educators, content creators, and individuals with visual impairments. Key Features and Functionality: - Multi-Language Support: Accommodates a wide array of languages, enabling users to produce audio content in their preferred language. - Variety of Voice Styles: Offers numerous natural-sounding voices, ensuring that the generated speech aligns with the desired tone and context. - Customizable Settings: Allows users to adjust speech speed and volume to meet specific requirements. - High Character Limit: Supports up to 20,000 characters per week on the free plan, with higher limits available in premium subscriptions. - Downloadable Audio Files: Enables users to download generated speech in MP3 format for offline use. - Cross-Device Compatibility: Accessible on various devices, including iPhones, laptops, and desktop computers, providing flexibility and convenience. Primary Value and User Solutions: Text to Speech.im addresses the need for accessible and efficient text-to-speech conversion by offering a user-friendly platform that produces high-quality audio outputs. It serves as a cost-effective alternative to hiring voice actors, making it ideal for creating voiceovers, audiobooks, and educational materials. Additionally, it enhances content accessibility for individuals with visual impairments or reading difficulties, ensuring that information is available to a broader audience.

Who Is the Company Behind Text to Speech.im?

Tipp

Tipp is an AI-powered platform designed to transform written content into personalized audio podcasts, enabling users to stay informed without the need for screen time. By aggregating various content sources such as newsletters, RSS feeds, emails, and web pages, Tipp curates and converts them into engaging audio episodes tailored to individual preferences. This innovative approach allows users to consume relevant information seamlessly during daily activities like commuting, exercising, or multitasking. Key Features and Functionality: - Content Aggregation: Tipp integrates with multiple sources, including RSS feeds, email newsletters, and saved web pages, to collect and organize content that matters to the user. - Personalized Curation: Users can define topics of interest, set up keyword tracking, and select specific content streams, ensuring that the generated podcasts are relevant and customized. - AI-Powered Audio Generation: Leveraging advanced text-to-speech technology, Tipp converts curated written content into natural-sounding audio, providing a high-quality listening experience. - Flexible Consumption: The platform offers a centralized hub for tracking news and updates, allowing users to listen to their personalized podcasts anytime and anywhere, reducing screen fatigue and enhancing productivity. Primary Value and User Solutions: Tipp addresses the challenge of information overload by streamlining content consumption into a manageable and personalized audio format. It empowers busy professionals, researchers, and lifelong learners to stay updated on their fields of interest without dedicating additional screen time. By converting diverse written materials into audio, Tipp enhances multitasking capabilities, reduces eye strain, and transforms routine activities into opportunities for continuous learning and engagement.

Who Is the Company Behind Tipp?

Toolscase Voice Studio

Toolscase Voice Studio at https://voice.toolscase.com is a free browser-based text-to-speech and speech-to-text studio, part of Toolscase ecosystem (35+ tools at toolscase.com, 108 PDF Tools at pdf.toolscase.com). Text-to-Speech: Free text to speech with natural voices and MP3 download. Type or paste text, choose a voice and hear it in seconds. Download MP3 for video, course or podcast with commercial use, no watermark. Powered by Kokoro-82M with 22 natural voices across 9 languages - English US/UK, Spanish, French, Hindi, Italian, Portuguese BR, Japanese, Mandarin Chinese. 14 female voices, 8 male voices, 9 American accent, 3 British accent. Controls for speed 0.5x-2x, pitch, pauses, chapter markers, multi-speaker assignment, background music mixing. Exports MP3/WAV. Speech-to-Text: Speech to text that you can actually edit. Turn interviews, meetings, lectures, voice notes and videos into accurate text. Every word timestamped and synced to audio, fixing a mistake takes one click. Powered by Whisper large-v3-turbo for transcription in ~100 languages with speaker ID, timestamps, word-level timestamps, translations, TXT & SRT/VTT export. Upload MP3, WAV, M4A, OGG/Opus, FLAC, WebM, MP4, MOV, WebM, or record or paste file link. Files deleted after 30 days. Pricing: Guest demo 3 free generations/day no signup. Free $0/mo 20,000 characters + 30 minutes transcription. Starter $9/mo 200k chars / 300 mins. Pro $29/mo 1M chars / 1500 mins. Business $79/mo 3M chars / 5000 mins. Alternative to ElevenLabs, Murf AI, Speechify, Descript, Otter.ai, Play.ht, LOVO AI, NaturalReader. Use cases: YouTubers, podcasters, course creators, developers, teams working with audio needing affordable TTS/STT with commercial rights.

Who Is the Company Behind Toolscase Voice Studio?

AI can help you find the answers. G2 helps you trust them.

Connect G2 to Claude or ChatGPT for answers grounded in G2's trusted reviews, comparisons, and pricing from real user insights.

How it works

Totemotech

TotemoTech is an AI-driven podcast delivering concise English summaries of Japanese technology news. By leveraging advanced AI technologies, it transforms Japanese tech stories into natural-sounding English audio, providing listeners with daily, digestible updates directly sourced from Japan. Key Features and Functionality: - AI-Generated Summaries: Utilizes OpenAI's GPT API to create accurate English summaries of Japanese tech news. - Natural-Sounding Speech: Employs ElevenLabs' text-to-speech API to produce human-like audio narrations. - Daily Updates: Offers brief, two-minute episodes covering the latest tech developments in Japan. - Accessible Platform: Hosted on GitHub Pages with a Jekyll-generated static site, ensuring a seamless user experience. - Open Source: The underlying code is available under the MIT license, promoting transparency and community collaboration. Primary Value and User Solutions: TotemoTech addresses the challenge of accessing timely and reliable Japanese tech news for English-speaking audiences. By automating the translation and narration process, it eliminates language barriers and provides an unbiased, efficient way to stay informed about Japan's technological advancements. Listeners can effortlessly integrate these brief updates into their daily routines, ensuring they remain up-to-date with minimal time investment.

Who Is the Company Behind Totemotech?

TTS.ai

TTS.ai is an advanced text-to-speech software designed to convert written text into natural-sounding speech. Utilizing cutting-edge artificial intelligence and deep learning technologies, TTS.ai offers high-quality voice synthesis that closely mimics human speech patterns and intonations. This makes it an ideal solution for applications such as audiobooks, virtual assistants, e-learning platforms, and more. Key Features and Functionality: - Natural-Sounding Voices: TTS.ai provides a diverse range of lifelike voices, ensuring a realistic auditory experience. - Multilingual Support: The software supports multiple languages and dialects, catering to a global audience. - Customization Options: Users can adjust speech parameters, including pitch, speed, and volume, to suit specific needs. - Integration Capabilities: TTS.ai offers APIs and SDKs for seamless integration into various applications and platforms. - Cloud-Based Service: As a cloud-based solution, TTS.ai ensures accessibility and scalability without the need for extensive hardware. Primary Value and User Solutions: TTS.ai addresses the need for high-quality, natural-sounding speech synthesis in various industries. By transforming text into human-like speech, it enhances user engagement, accessibility, and content consumption. For businesses, it streamlines content creation processes, reduces costs associated with voice-over production, and broadens audience reach by supporting multiple languages. Additionally, TTS.ai's customizable features allow for tailored user experiences, making it a versatile tool for developers and content creators alike.

Who Is the Company Behind TTS.ai?

TTS Buddy

TTS Buddy is a text-to-speech SaaS for teams, developers, educators, and accessibility workflows. It converts text, PDFs, documents, and webpages into natural downloadable audio using 300+ voice options and 30+ language modes. Users can work through the web app, Chrome extension, CLI, Listen Link sharing, and REST API, with a free plan and request sizes up to 500,000 characters.

Who Is the Company Behind TTS Buddy?

Ttslabs

TTSLabs is an AI-powered Text-to-Speech (TTS) service tailored for Twitch streamers, enabling them to enhance audience engagement through customizable voice alerts and sound clips. With access to over 80 unique voices, streamers can personalize their TTS experience, integrating seamlessly with platforms like Streamlabs and StreamElements. The service offers advanced features such as a dedicated desktop application for easy management, faster-than-real-time audio processing, and robust profanity filters, ensuring a dynamic and interactive streaming environment. Key Features and Functionality: - Extensive Voice Library: Access to over 80 custom voices, including official, community, and classic options, allowing streamers to tailor their TTS alerts to match their brand and audience preferences. - Dedicated Desktop Application: Provides seamless management and playback of TTS alerts, enabling easy customization of prices, voices, and sound clips. - Rapid Audio Processing: Generates 20 seconds of audio in less than 3 seconds, ensuring minimal delay between viewer interactions and audio playback. - Viewer Guidance: Offers a custom guide for viewers to check enabled alerts, voices, sound clips, and minimum values for TTS, enhancing user engagement. - Platform Integration: Syncs with Streamlabs and StreamElements, allowing control of TTS donations through the streamer's dashboard. - Advanced Profanity Filters: Allows streamers to manage which donations are permitted through preset levels of profanity and custom filters, maintaining a respectful streaming environment. - Sound Clips: Enables the addition of unique sound clips to enhance the creativity of TTS donations, providing a more entertaining experience for viewers. Primary Value and User Solutions: TTSLabs addresses the need for Twitch streamers to create a more interactive and personalized streaming experience. By offering a vast array of customizable voices and sound clips, along with seamless integration with popular streaming platforms, TTSLabs empowers streamers to engage their audience more effectively. The rapid audio processing and advanced management tools ensure that streamers can maintain a dynamic and responsive environment, fostering viewer participation and enhancing overall stream quality.

Who Is the Company Behind Ttslabs?

TTSReader

TTSReader is a text to speech platform that turns written content into natural-sounding audio. Businesses and creators use it to produce voiceovers, audio versions of articles and documents, and listenable content for people who prefer to hear rather than read. Start in the web player at ttsreader.com: no install needed. Key features: - About 580 natural AI voices in 80+ languages, plus free unlimited reading with your device's voices - MP3/WAV export with a commercial license and full ownership of the audio - Import pasted text, web pages, PDF, Word (DOCX) and EPUB files - Pronunciation dictionary for names, brands and technical terms; multi-voice dialogs - Text to speech API (Premium) to automate audio generation - Personal podcast (RSS) feed of your exported audio - Works in the browser, as a Chrome/Edge extension, and on iPhone, iPad, Mac and Android Pricing: a free plan with device voices; Premium from $10.99/month or $99/year, or one-off credit packs without a subscription. Made by Well Source, running since 2015.

Who Is the Company Behind TTSReader?

TTSStudio

TTSStudio is an advanced text-to-speech platform that enables users to convert written text into natural-sounding speech. Designed for a wide range of applications, TTSStudio offers a user-friendly interface and a variety of voice options to cater to diverse needs. Key Features and Functionality: - High-Quality Voices: Provides a selection of lifelike voices in multiple languages and accents, ensuring versatility for global users. - Customization Options: Allows users to adjust speech parameters such as pitch, speed, and volume to achieve the desired output. - Integration Capabilities: Offers APIs and SDKs for seamless integration into various applications, including e-learning platforms, assistive technologies, and multimedia projects. - Cloud-Based Service: Operates entirely online, eliminating the need for software installation and enabling access from any device with internet connectivity. - Scalability: Accommodates projects of all sizes, from individual use to enterprise-level applications, with flexible pricing plans. Primary Value and User Solutions: TTSStudio addresses the need for high-quality, customizable text-to-speech solutions across various industries. It enhances accessibility for individuals with visual impairments, supports language learning by providing accurate pronunciations, and enriches content creation by adding voiceovers to videos and presentations. By offering an intuitive platform with diverse voice options and integration capabilities, TTSStudio empowers users to create engaging and inclusive auditory experiences efficiently.

Who Is the Company Behind TTSStudio?

tunyn

Tunyn is an innovative platform that transforms lengthy articles, blogs, and news into concise audio summaries, enabling users to stay informed efficiently. By converting text into brief audio snippets, Tunyn caters to individuals seeking to absorb information on the go, whether during commutes, workouts, or daily routines. Key Features and Functionality: - Audio Summarization: Converts extensive written content into short, digestible audio summaries. - Wide Content Support: Supports a variety of content types, including articles, blogs, and news. - User-Friendly Interface: Offers an intuitive platform for easy navigation and use. - Accessibility: Provides an alternative to traditional reading, accommodating diverse user preferences. Primary Value and User Solutions: Tunyn addresses the challenge of information overload by offering a time-efficient method to consume content. It caters to busy individuals who struggle to keep up with extensive reading materials, providing them with concise audio summaries that fit seamlessly into their daily lives. This approach enhances productivity and ensures users remain informed without dedicating significant time to reading.

Who Is the Company Behind tunyn?

Uberduck

Uberduck is an AI-driven platform that empowers creators, developers, and businesses to generate realistic and expressive synthetic vocals. It offers a suite of tools for text-to-speech, voice cloning, and music generation, enabling users to produce high-quality audio content without the need for professional recording equipment or voice talent. With support for over 70 languages and a diverse range of musical styles, Uberduck caters to a global audience seeking innovative audio solutions. Key Features and Functionality: - Text-to-Speech (TTS): Convert written text into natural-sounding speech, singing, or rapping, utilizing a vast library of voices, including celebrity impressions and unique character voices. - Voice Cloning: Create custom voice models by cloning any voice in seconds, allowing for personalized and unique audio content generation. - Music Generation: Instantly produce professional-sounding tracks with AI-generated lyrics and vocals, suitable for various applications such as video game soundtracks, brand jingles, and social media content. - API Access: Integrate Uberduck's capabilities into applications, enabling seamless voice synthesis and music generation within existing workflows. - Multi-Language Support: Generate audio content in over 70 languages, broadening the scope for global applications and diverse user bases. Primary Value and User Solutions: Uberduck addresses the challenges of creating high-quality audio content by providing accessible, AI-powered tools that eliminate the need for expensive recording equipment and professional voice talent. It enables users to produce engaging and personalized audio for marketing campaigns, entertainment, education, and more. By offering features like voice cloning and music generation, Uberduck empowers creators to explore new creative possibilities and streamline their content production processes.

Who Is the Company Behind Uberduck?

  • Seller: Uberduck
  • Year Founded: 2021
  • HQ Location: Seattle, US
  • LinkedIn® Page: www.linkedin.com
    2 employees on LinkedIn®

Vaanee AI Engine

Vaanee AI Engine is an advanced voice cloning and generative speech platform designed to revolutionize audio content creation. Leveraging cutting-edge artificial intelligence, it enables users to produce hyper-realistic voiceovers, clone voices with remarkable accuracy, and dub videos across multiple languages. This versatile tool caters to a wide range of applications, including content creation, education, marketing, and entertainment, by providing natural-sounding speech that captures the nuances and emotions of the original speaker. Key Features and Functionality: - Text-to-Speech (TTS): Converts written text into natural, expressive speech, enhancing accessibility and engagement. - Voice Cloning: Creates digital replicas of any voice with just a few samples, preserving unique vocal characteristics. - Speech-to-Speech Translation: Offers real-time voice translation while maintaining the original voice's distinct features. - AI Video Dubbing: Seamlessly dubs videos into multiple languages with precise lip-syncing, broadening audience reach. - Multi-Language Support: Supports over 50 languages and accents, including numerous Indian and global languages, facilitating global communication. - Voice Customization: Allows adjustments to pitch, pace, tone, and personality to create the perfect voice for various needs. - Contextual Emotions: AI interprets the mood and conveys appropriate emotions, resulting in authentic and engaging content. Primary Value and Solutions Provided: Vaanee AI Engine addresses the challenges of producing high-quality, multilingual audio content by offering a suite of tools that simplify and enhance the voice generation process. It eliminates the need for traditional, time-consuming recording sessions, enabling creators to generate professional-grade voiceovers and dubbing efficiently. By supporting a vast array of languages and providing customizable voice options, Vaanee AI empowers users to connect with diverse audiences, break language barriers, and deliver emotionally resonant content across various platforms.

Who Is the Company Behind Vaanee AI Engine?

  • Seller: Vaanee
  • Year Founded: 2023
  • HQ Location: N/A
  • LinkedIn® Page: www.linkedin.com
    23 employees on LinkedIn®

Veritone Voice

Veritone Voice is an advanced AI-driven Voice-as-a-Service (VaaS) solution designed to produce hyper-realistic synthetic voices for a variety of applications. It enables users to create, manage, and monetize custom voice models, facilitating the production of lifelike voice content without the need for traditional recording sessions. This technology is particularly beneficial for media companies, brands, broadcasters, podcasters, and advertisers seeking to generate personalized and localized audio content efficiently. Key Features and Functionality: - Custom AI Voice Models: Users can clone voices, including those of celebrities and public figures (with consent), to produce voice-over content using text-to-speech or speech-to-speech inputs. - Enterprise Workflows: The platform offers tools to automate voice content creation, enhancing metadata and generating dialogue to optimize voice automation outputs at scale. - API and Real-Time Voice Integration: Veritone Voice provides a robust API that allows seamless integration of AI voice capabilities into various applications, enabling real-time voice generation and automation. - Stock and Premium Voices: Users have access to a library of over 300 stock voices and 70 premium options, supporting more than 150 languages, with customization options for intonation, gender, dialect, and accent. Primary Value and User Solutions: Veritone Voice addresses the growing demand for rapid and scalable voice content production by eliminating the logistical challenges associated with traditional voice recording. It empowers users to create authentic, localized, and personalized audio content, thereby expanding audience reach and engagement. The platform's automation capabilities reduce production time and costs, while its integration options provide flexibility for various applications, from advertising and broadcasting to e-learning and podcasting. By offering a secure and ethical approach to synthetic voice creation, Veritone Voice ensures compliance and protection for voice identities, making it a comprehensive solution for modern voice content needs.

Who Is the Company Behind Veritone Voice?

  • Seller: Veritone Inc.
  • Year Founded: 2014
  • HQ Location: Denver, US
  • Twitter: @veritoneinc
    4,508 Twitter followers
  • LinkedIn® Page: www.linkedin.com
    409 employees on LinkedIn®
  • Ownership: NASDAQ: VERI
Bijou Barry
BB
Researched and written by Bijou Barry
Updated April 9, 2026